
- Published
- Feb 20, 2026
- Updated
- Oct 27, 2026
- Reading time
- 14 min read
Cross-Device Frequency Capping: How to Audit Actual Exposure
Audit frequency caps across display, CTV, and publishers. Learn why averages mislead, how identity coverage matters, and how to test actual campaign exposure.
In this guide (13 sections)
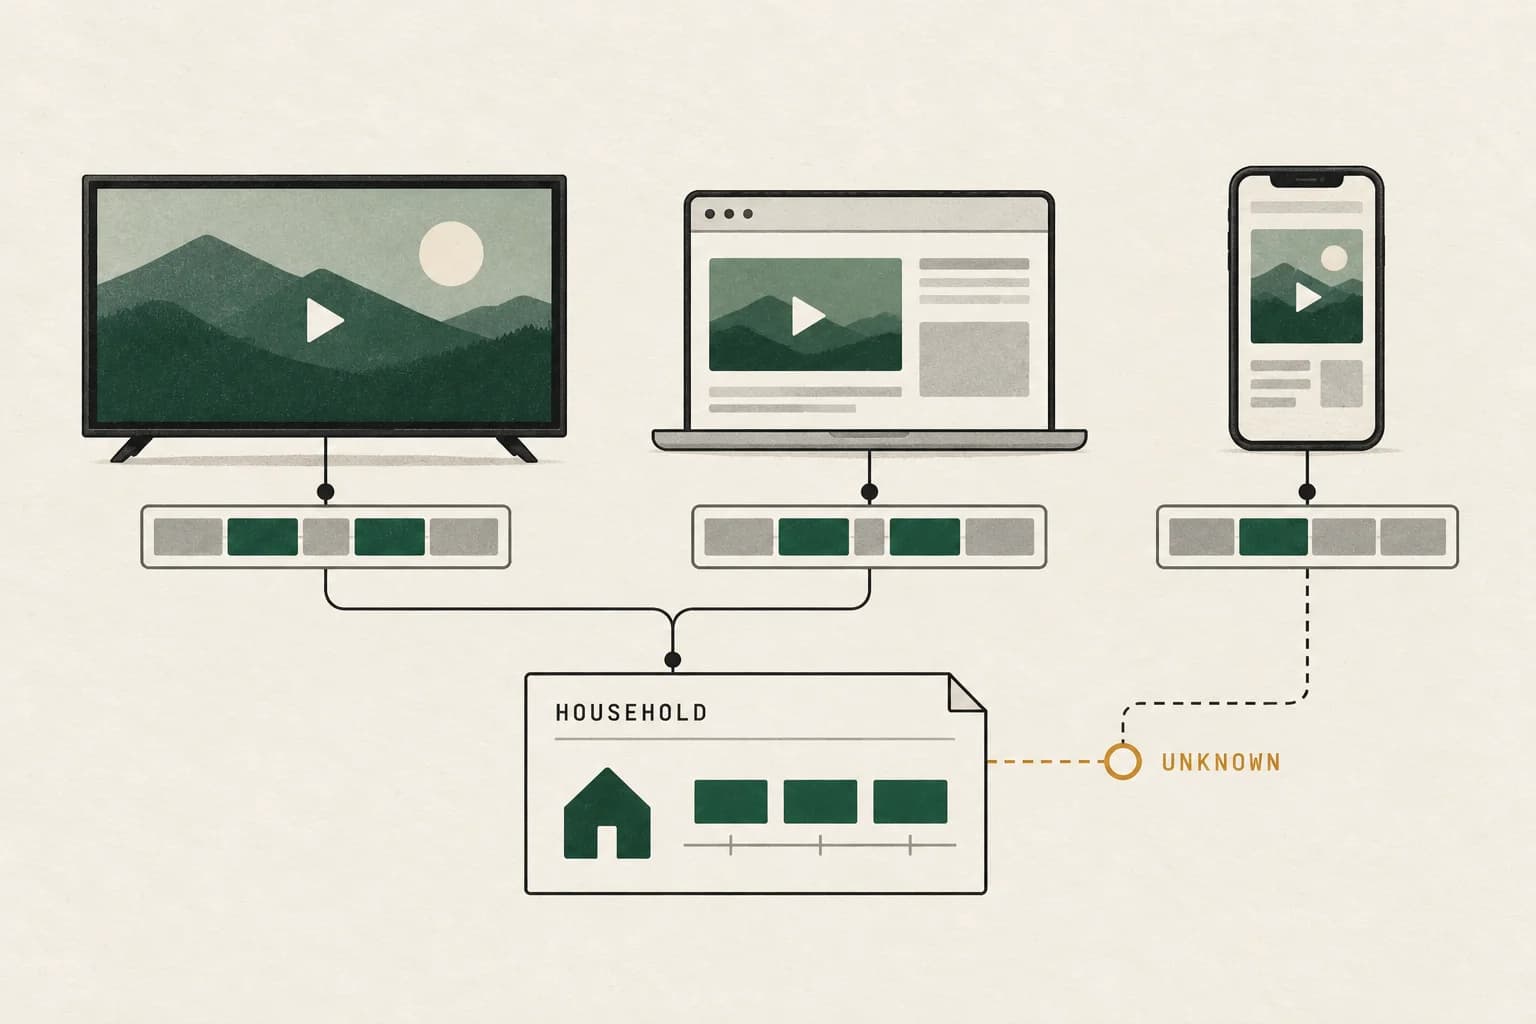
Your campaign has a frequency cap of three per day. The report shows an average of 2.4. That average does not tell you whether anyone received more than three impressions, whether the cap applied across publishers, or whether it counted a browser, device, person, or household.
A frequency audit needs four things: the configured rule, its identity unit, the observed distribution, and a coverage statement. This guide shows how to collect them and test actual exposure across display, CTV, and programmatic guaranteed deals.
This is a recurring reader problem. In a March 2026 r/adops question, a buyer asked whether impressions divided by reach could reveal a vendor's cap. An earlier cross-publisher PG discussion produced conflicting answers. The appropriate response is to verify current platform behavior and deal terms, then test the measurement scope.
Define the cap before evaluating the report#
A useful frequency rule is more specific than “three per day.” Write it as:
At most [counted event] per [identity unit], across [campaign scope], during [window], subject to [supported inventory and delivery policy].
For example, a hypothetical rule could be “at most three counted impressions per supported device identifier, across these campaign line items, during a rolling 24-hour window.” That is different from three per household across all media in a calendar day.
Record these fields before launch:
| Field | Question to settle |
|---|---|
| Event | Served, viewable, video start, or another defined exposure? |
| Identity | Browser, device, signed-in account, modeled person, or household? |
| Scope | Creative, line item, insertion order, campaign, or shared frequency group? |
| Time | Calendar day, rolling 24 hours, week, or another supported window? |
| Inventory | Which web, app, audio, and CTV integrations participate? |
| Missing identity | Exclude, model, apply a local rule, or serve without this cap? |
| Priority | Hard constraint or optimization subject to a reservation obligation? |
| Evidence | Configuration export, change log, and observed report available? |
Two publishers each enforcing three per day can collectively deliver six to the same measurable identity. Their local rules may both be respected while your desired campaign-wide limit is not implemented.
A cap also sets a ceiling within its scope. It does not promise a minimum number of exposures to every reached person. Buyers raised this distinction in a June 2026 programmatic discussion. Avoid treating low average frequency as evidence that a maximum cap is broken.
Check what the cap counts and where it applies
An average frequency does not show whether an individual exceeded the cap. Discuss the identity unit and scope your reports can measure.
Discuss delivery measurementA short inquiry to scope relevant options; no campaign access is needed.
Browser, device, person, and household are different units#
The same impression can appear in several analyses with different denominators. Naming the unit prevents a false comparison.
| Unit | What the analysis groups together | Important limitation |
|---|---|---|
| Browser identifier | Events associated with a browser-level identifier | One person may use multiple browsers or reset identifiers |
| Device identifier | Events linked to a supported device identity | A shared TV or tablet is used by more than one person |
| Account | Events associated with a permitted signed-in account | Account sharing and separate logins affect interpretation |
| Modeled person | An estimate produced under a declared reach model | Model coverage and uncertainty must be disclosed |
| Household | Events assigned to a household definition | Household exposure does not establish who watched |
A TV impression and a phone impression cannot simply be assigned to one person because they share an IP address. Google's network explanation notes that many computers can share an address. A home network can also contain several people, guests, and devices that are not currently in use.
Where permitted, identity systems may use account information or other declared linkages. Ask how the linkage was established, its applicable period, and what happens when it is uncertain. “Deterministic” should describe the evidence relationship, not promise that a shared account equals an individual viewer.
For a deeper discussion of the unit itself, read household identity in streaming measurement. Keep household and person-level outputs labeled separately in the campaign report.
Current platform behavior matters more than an old forum answer#
A platform may expose frequency settings at several hierarchy levels and use different rules by inventory type. Treat screenshots of the cap field as configuration evidence, then verify its documented effect.
Google's current DV360 frequency-cap documentation describes campaign, insertion-order, and line-item scopes, with available identifiers and modeling used across inventory. It also distinguishes behavior by buying mode. That is a platform-specific implementation, not a guarantee about every DSP.
The same documentation describes identifier-dependent CTV behavior. Confirm which identifiers are actually passed on each integration and what happens when a supported identifier is absent. Do not assume a setting visible in the interface proves coverage of every app in the campaign.
Programmatic guaranteed: check delivery priority explicitly
DV360's PG reach guidance says the system prioritizes meeting the deal's spend terms and then optimizes toward the campaign-level cap using available inventory. A narrow audience combined with a restrictive cap can therefore create a conflict with guaranteed delivery.
Ask your DSP and publisher to document:
- Which party makes the final serving decision?
- Which cap scopes can prevent delivery, and which are best effort?
- Whether identity is shared or usable across the relevant publishers.
- What happens when the campaign cap conflicts with reservation terms.
- Which report shows passed opportunities and actual exposure.
Obtain the answer for the specific deal and current integration. A claim about DV360 should not be copied into a TTD or Amazon DSP brief. If you require a strict cross-publisher ceiling, settle the contractual and technical mechanism before agreeing to guaranteed volume.
Why average frequency cannot prove cap compliance#
Average frequency is a ratio. For a directly observed identity population:
Average frequency = impressions assigned to that population
                    / distinct reached identities in that population
Its numerator and denominator must refer to the same scope, event, identity, and interval. Do not divide all campaign impressions by the reachable identities from only the measurable portion.
Here is an original hypothetical daily dataset. Both campaigns reach 100 devices and record 240 impressions. Assume the audit threshold is three impressions per device for this example only.
| Observed daily frequency | Campaign A devices | Campaign B devices |
|---|---|---|
| 1 impression | 0 | 80 |
| 2 impressions | 60 | 0 |
| 3 impressions | 40 | 0 |
| 8 impressions | 0 | 20 |
| Total reached devices | 100 | 100 |
| Total impressions | 240 | 240 |
| Average | 2.4 | 2.4 |
Campaign A has no observed device above three. Campaign B has 20 devices above three, accounting for 160 of its impressions. The identical average hides very different distributions.
For Campaign B:
Observed devices above threshold = 20 / 100 = 20%
Observed impressions on above-threshold devices = 160 / 240 = 66.7%
Observed impressions beyond threshold = 20 x (8 - 3) = 100
Beyond-threshold impression share = 100 / 240 = 41.7%
These are four different metrics. The second includes all impressions delivered to a device whose final count exceeds the threshold. The third counts only the exposures beyond it. Label them clearly before discussing avoidable spend.
Even this distribution does not establish a platform defect until the event, identity unit, window, cap scope, and reservation policy match the rule. It identifies where the investigation should begin.
Build a report that exposes the high-frequency tail#
Ask for a distribution at the finest privacy-permitted level, or the platform's aggregate frequency bins when event-level access is unavailable. A useful report contains:
- The complete campaign impression count.
- Impressions eligible for the identity-based analysis.
- Reached identities under the declared definition.
- Frequency bins, including the range above the agreed audit threshold.
- The share of impressions and identities in those bins.
- A separate unknown or unsupported population.
- Report date, data maturity, and any model qualifications.
DV360's reach and frequency explanation distinguishes modeled unique reach and frequency from cookie counting, includes co-viewing considerations, and documents reporting limitations. If you use a modeled people metric, retain that label. Do not present its estimate as a directly observed device census.
For cumulative bins such as 1+, 2+, and 3+, the bins overlap. You cannot sum them as though they were exclusive groups. Where definitions permit, exact-frequency counts can be derived by subtracting adjacent cumulative bins. An open-ended highest bin still cannot reveal each identity's exposure count.
If privacy thresholds suppress a slice, report it as unavailable. A dash is not zero, and combining a partially suppressed denominator with a full numerator can produce a misleading frequency.
Show measurement coverage beside every conclusion#
Suppose a hypothetical campaign records 1,000,000 impressions. Of those, 650,000 can be assigned to the supported identity analysis and 350,000 cannot.
Identity-assigned impression coverage = 650,000 / 1,000,000 = 65%
Unknown or unsupported impression share = 35%
A distribution built from the 650,000 observations describes that covered population. It does not prove that the other 350,000 have the same distribution. Missing identity can be concentrated in particular apps, devices, countries, or publishers.
Split coverage by those dimensions where reporting allows. A campaign-level percentage can conceal that one publisher is almost entirely outside the audit. State whether the unknown population was excluded by the serving rule, measured through a model, or present only in aggregate reporting.
For CTV identifiers, use current documentation. IAB Tech Lab's current IFA-type extension distinguishes device-, publisher-, SSP-, and session-provided identifiers. A short-lived session identity should not be treated as a persistent household identity across weeks.
Respect permitted signal use. Do not fill a coverage gap by inventing a stable identifier, fingerprinting around restrictions, or stitching personal data without an authorized basis. The honest result may be a bounded estimate rather than a complete individual-level count.
Do not sum publisher reach to estimate campaign reach#
Suppose publisher A reports 40,000 reached identities and publisher B reports 35,000. Adding them produces 75,000 publisher-reach observations. It does not establish 75,000 unique campaign viewers, since some people may appear in both populations.
Likewise, dividing combined impressions by that sum understates frequency whenever overlap exists. The denominator contains duplicate people or devices, potentially under different identifiers.
Google's Reach reports documentation explicitly cautions against summing reach across reports or hierarchy levels. Use a supported deduplicated campaign report, a properly scoped measurement study, or a labeled overlap estimate. If cross-publisher deduplication is unavailable, report publisher-level frequency with that limitation.
Do not silently mix modeled people reach from one source with device reach from another. Two columns labeled “unique” can still count different things.
A practical test plan for a frequency audit#
Step 1: capture the configuration
Save cap settings and hierarchy membership, with effective timestamps. Include all relevant campaign, order, line-item, creative, publisher, and deal identifiers. Record exceptions and any changes during the reporting interval.
If different teams control different parts of the buy, request their evidence in the same template. A spreadsheet of agreed settings is a starting point; an exported effective configuration or audited change record is stronger evidence of implementation.
Step 2: align the counting window
Use the same window as the rule. A seven-day report can include several daily caps and should not be tested against a one-day ceiling. Calendar-day and rolling-window results can differ near midnight.
For a rolling limit, an event sequence or a supported rolling-window report is required. A calendar-day bucket alone cannot prove that every rolling 24-hour interval respected the rule.
Step 3: inspect authorized controlled sessions
Where permitted, run documented test sessions on supported web and CTV integrations. Record the identity scope available to the measurement system, event time, and source. Keep tests out of commercial reporting where the integration supports test labeling.
This can reveal an unrecognized device, duplicated event, or reset between app sessions. It does not prove production-wide compliance: a small controlled test covers only its specific devices, identifiers, and inventory conditions.
Step 4: analyze production aggregates
Compare the frequency distribution with coverage, late data, and cap exceptions. Inspect the highest-exposure slices first. Check duplicate impression records and identity changes before classifying excess exposure as a serving failure.
Use the CTV discrepancy workflow when two systems disagree on the underlying impressions. Frequency cannot be reconciled while each team counts a different event population.
Step 5: change one lever and evaluate the tradeoff
Choose a bounded intervention such as consolidating eligible buys under a supported shared scope, correcting a hierarchy assignment, or renegotiating a publisher-level cap. Define the expected effect in advance.
Track reach, exposure distribution, delivered volume, cost, and business outcomes. A lower high-frequency tail accompanied by severe underdelivery may require a broader eligible audience or different inventory arrangement. Do not claim improved efficiency solely because the average fell.
Choose a cap through a campaign experiment#
There is no universal ideal number that follows from the existence of a frequency report. A product launch, reminder campaign, and limited local audience can have different objectives and constraints.
Start with an explicit objective and a feasible exposure range. Where scale permits, compare otherwise similar groups under different frequency policies. Keep creative, audience eligibility, timing, and inventory comparable, and allow enough data for the selected outcome.
Distinguish association from incrementality. People with more impressions may differ because they use more eligible media, are easier to identify, or were more likely to convert already. A chart showing higher conversion among high-frequency viewers does not establish that extra exposures caused the conversions.
Record the decision even when the test is inconclusive: what was observed, coverage, uncertainty, and the next experiment. Avoid presenting an arbitrary threshold as an industry fatigue law.
Copyable frequency audit brief#
Campaign / audit interval / time zone:
Business objective:
Configured cap and effective timestamps:
Counted exposure event:
Identity unit and source:
Hierarchy and shared campaign scope:
Calendar or rolling window:
Participating publishers, deals, and environments:
PG delivery-priority exceptions:

Total impressions:
Identity-assigned impressions and coverage:
Unknown / unsupported impressions:
Observed or modeled reached population:
Frequency distribution and bin definitions:
Above-threshold identity share:
Beyond-threshold impression count:
Report maturity and suppression notes:

Evidence of configuration:
Observed exception samples or aggregate slices:
Potential duplicate or identity-reset explanations:
Proposed bounded change:
Success condition and observation period:
Owner and follow-up date:
Frequently asked questions#
Can a frequency cap work across display and CTV?
A platform can support shared controls across eligible inventory, but the result depends on the scope, identifiers, modeling, and missing-identity policy. Confirm supported behavior in the current documentation and test your actual integrations. A per-device control is not automatically a per-person control.
Can a campaign cap apply across several PG publishers?
That depends on the DSP, deal, serving decision, identity availability, and reservation policy. Obtain a current documented answer for each integration. Some campaign-level controls optimize toward a limit while prioritizing guaranteed delivery.
Does impressions divided by reach reveal the cap?
It gives an average when numerator and denominator align. It does not reveal a maximum, configuration, or compliance distribution. Use frequency bins and effective settings to evaluate the ceiling.
Why is reported frequency higher than my cap?
Check event definitions, identity unit, window, scope, duplicate records, and deal exceptions. A served-impression report may not match a cap that counts a different exposure event. A device-based rule also cannot be directly judged against a household report.
Can independent measurement enforce a DSP cap?
Measurement and serving control are separate responsibilities. Establish what the measurement integration can observe and what the buying platform can act on. A report can support an investigation without having authority to stop delivery.
For a linear-plus-streaming review, separate overlap from incremental purchases.
Make the next frequency decision reviewable#
Bring a rule, distribution, and coverage statement to the next campaign review. Those three artifacts make it possible to distinguish a configuration problem, identity limitation, contractual exception, and genuine exposure issue.
Review AdProof, explore measurement solutions, or discuss your frequency audit. Start with the identity and event definitions above so the required scope can be assessed before any conclusions are promised.
Sources and research notes#
Researched on 25 October 2026. Primary sources are the current Google pages linked beside each platform-specific claim and IAB Tech Lab's IFA-type extension. Original reader-question references also include cross-channel capping and frequency settings and reporting. Forum threads establish practical reader questions and sometimes contain conflicting or dated advice. The arithmetic examples and audit plan are original hypothetical illustrations, not campaign results. No universal recommended cap, verified identity coverage, or AdProof serving-control capability is asserted.
Check what the cap counts and where it applies
An average frequency does not show whether an individual exceeded the cap. Discuss the identity unit and scope your reports can measure.
Discuss delivery measurementA short inquiry to scope relevant options; no campaign access is needed.