
- Published
- Mar 10, 2026
- Updated
- Oct 31, 2026
- Reading time
- 24 min read
IVT Rates Explained: Denominators, Filtering, and Evidence
Understand invalid traffic rates, GIVT and SIVT, pre-bid filtering, and false positives. Use worked examples and an evidence checklist to audit your reports.
In this guide (15 sections)
An invalid traffic report says 50%. Your website received 10,000 visits, and the report identifies 500 problematic records. Before you block a source or dispute an invoice, you need to establish what that percentage divides by and what those records actually represent.
This guide explains how to audit an IVT rate, reconcile received and filtered counts, and investigate suspicious activity without treating every unfamiliar network or missing signal as fraud. It includes a worked example and a copyable evidence request.
A commenter in a September 2026 r/adops discussion raised this denominator problem using a hypothetical subset. The tool author replied that all traffic was scanned. The exchange identifies a reporting question, not proof that the tool sampled incorrectly or misclassified traffic.
First establish what your report means by invalid#
Invalid traffic is a measurement classification. It does not automatically establish deliberate fraud, the identity of an attacker, or the amount of money recoverable under a contract.
For example, Google's AdSense definition includes artificially inflated impressions or clicks and covers accidental clicks as well as intentional fraud. A genuine person can produce an invalid interaction. A legitimate crawler can generate activity that should not be counted as an advertising audience.
Keep these questions separate:
| Question | Evidence required |
|---|---|
| Was an event received? | Receipt record and timestamp |
| Did it meet the definition of the measured event? | Event-trigger and counting rules |
| Was it classified as invalid? | Applicable classification and supporting evidence |
| Was it excluded from a reported metric? | Filter policy and report stage |
| Was it excluded from billing? | Contract, billing rules, and adjustment record |
| Was someone acting deceptively? | Additional evidence of conduct and intent |
A low conversion rate, high completion rate, or absent mouse movement can justify investigation. Each is a weak standalone basis for an accusation. A CTV remote does not behave like a desktop mouse, and a poorly matched campaign can attract real people who never buy.
Use the advertising metrics guide if your teams are mixing requests, impressions, clicks, visits, and conversions. An IVT percentage computed on requests cannot be directly compared with one computed on rendered impressions.
Understand the denominator behind your IVT rate.
Compare received, eligible, invalid and accepted counts before interpreting a percentage.
Discuss traffic measurementA measurement discussion, with scope confirmed before any next step.
GIVT and SIVT describe detection requirements#
The MRC's June 2020 IVT standards addendum distinguishes general invalid traffic, or GIVT, from sophisticated invalid traffic, or SIVT.
GIVT involves routine filtration using lists or standardized checks. SIVT addresses harder cases requiring deeper analysis, corroboration, or intervention. These categories do not mean harmless versus criminal, and a larger signal count does not establish SIVT capability.
Practical questions for a provider are more useful than a feature label:
- Which measurements and environments does the assessment cover?
- What is excluded before the report starts counting?
- Which results are GIVT, SIVT, uncertain, or outside coverage?
- How are overlapping classifications deduplicated?
- How can an affected publisher request review?
Ask for the scope of any claimed accreditation, including the service, metric, and environment. An accreditation claim for one service should not be extended to every product or integration offered by the same company.
The MRC's April 2024 interim update adds guidance on privacy, property-level assessment, and CTV inventory mismatch. It explicitly distinguishes known invalid data-center activity from legitimate routing and virtual-machine use. A network category alone needs context, and unavailable personal signals do not grant permission to bypass privacy restrictions.
The denominator audit: one number, three different rates#
Here is an original hypothetical example. These numbers illustrate reporting arithmetic; they are not an AdProof study, a vendor result, or an industry benchmark.
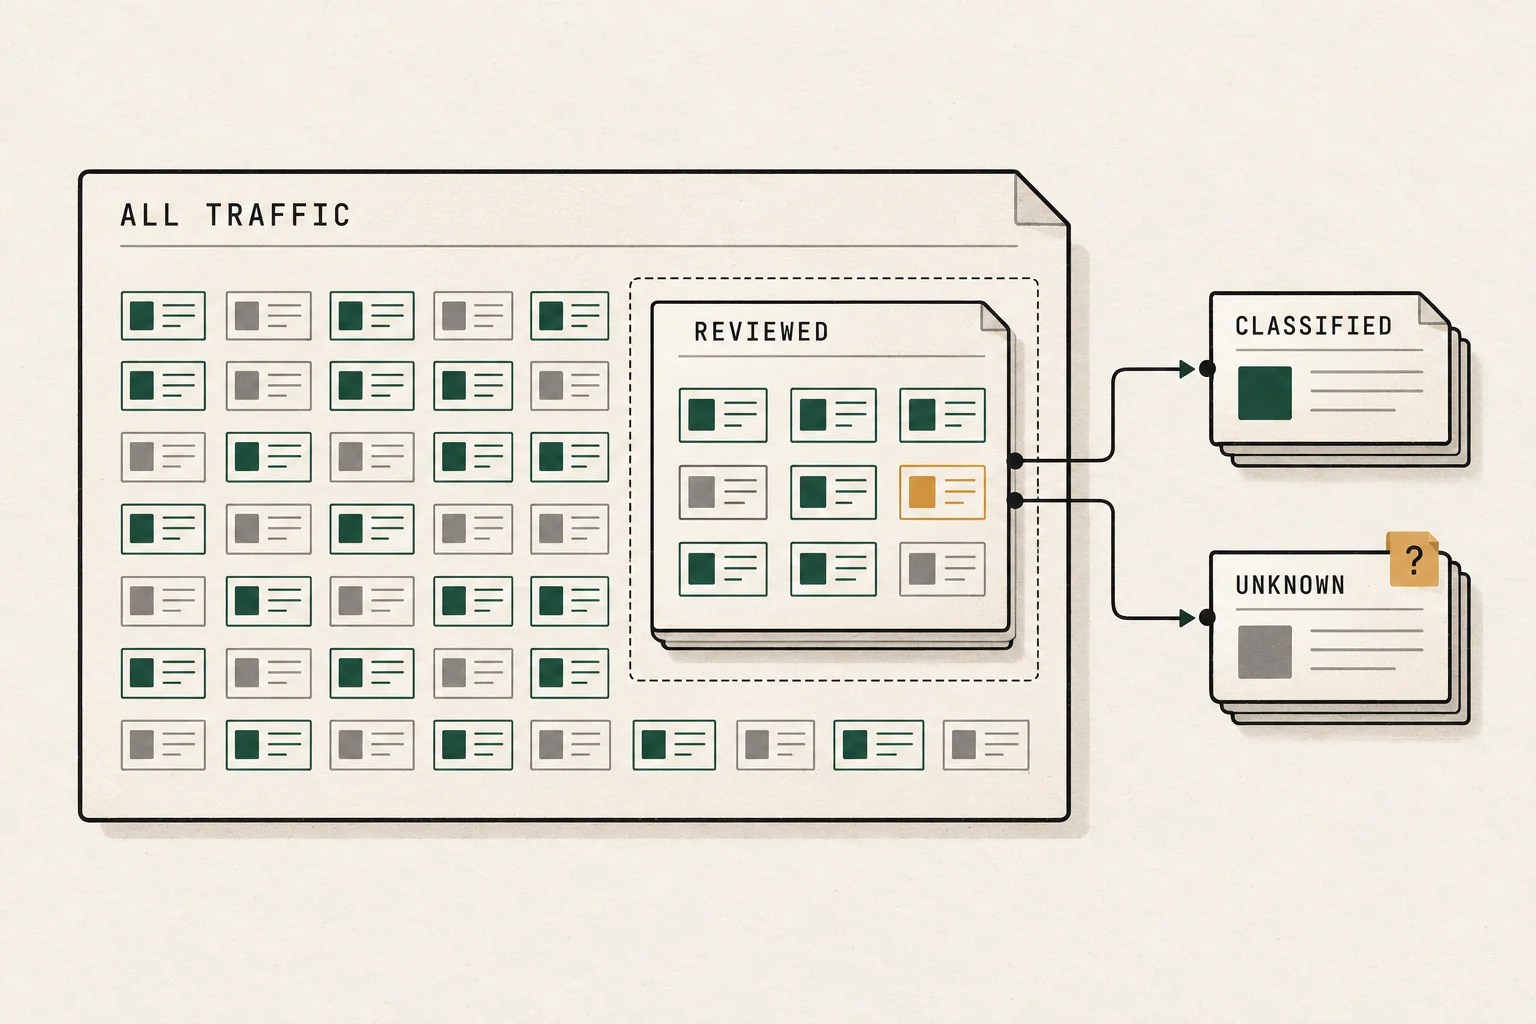
Suppose your system receives 10,000 eligible event records. A screening step routes 1,000 to enhanced review. Review classifies 500 as invalid and clears 500. The remaining 9,000 never enter enhanced review.
Received eligible records:        10,000
Sent to enhanced review:           1,000
Confirmed invalid within review:     500
Cleared within review:               500
Outside enhanced review:           9,000

Invalid among enhanced review = 500 / 1,000 = 50%
Detected invalid among all records = 500 / 10,000 = 5%
Enhanced review coverage = 1,000 / 10,000 = 10%
The 50% rate describes the selected subset. The 5% rate describes detected invalid records as a share of all eligible records. Neither proves that exactly 5% of the entire population was invalid: the classification status of the other 9,000 depends on what the screening step established.
If the screen genuinely classifies all 10,000 and escalates only difficult cases, describe that workflow. If it merely selects high-risk records without classifying the rest, preserve an unknown or not-reviewed status. Do not silently turn “not flagged” into “verified human.”
Why you cannot extrapolate a risk-selected subset
A risk-selected subset is deliberately enriched for suspicious events. Its invalid rate cannot be projected onto the entire population as though it were a random sample.
In this example, multiplying the 50% review rate by all 10,000 records would suggest 5,000 invalid records. Nothing in the selection method supports that inference. Conversely, declaring the unreviewed 9,000 clean would overstate what was checked.
Ask whether the provider uses a census, random sampling, stratified sampling, or risk-based selection. If a report estimates population IVT from a sample, request the sampling design, weighting, uncertainty, and population to which the estimate applies. An estimate and a directly counted exclusion should have different labels.
Write the metric in one sentence
Before accepting a dashboard percentage, complete this statement:
Of [denominator event type] recorded for [scope and interval], [numerator count] met [classification rule] as of [processing time], across [measurement coverage].
If that sentence cannot be completed, the percentage is not ready for a budget or billing decision.
Reconcile received, eligible, invalid, and accepted counts#
Do not assume “raw,” “gross,” and “net” have identical definitions across vendors. A collector's raw requests may include retries and malformed calls that were never eligible impressions.
Build a mutually exclusive ledger before comparing totals. Another hypothetical example:
| Stage or final bucket | Records | Meaning in this example |
|---|---|---|
| Received tracking requests | 12,000 | Everything received by the collector |
| Duplicate requests | 1,000 | Repeat records removed before event counting |
| Other ineligible requests | 1,000 | Calls that do not meet the defined event rules |
| Eligible measured events | 10,000 | Population used for this IVT comparison |
| GIVT, exclusively allocated | 200 | Events assigned to this first exclusion bucket |
| SIVT, exclusively allocated | 300 | Events assigned after avoiding GIVT overlap |
| Unclassified | 400 | Events with an unresolved decision |
| Accepted after these checks | 9,100 | Remaining eligible events under this example's policy |
The eligible population reconciles: 200 + 300 + 400 + 9,100 = 10,000. The request population reconciles separately: 1,000 + 1,000 + 10,000 = 12,000.
This ledger is an analytical template, not a replacement for the MRC's formal gross-metric requirements. Confirm where your measurement definition begins. Ask whether accepted reporting includes unresolved records, and disclose that policy.
If reason-code totals exceed invalid-event totals, ask whether one event can have multiple reasons. A single event with three flags is still one event. Maintain a unique excluded-event count alongside diagnostic flag counts.
This distinction is especially useful when publisher and buyer CTV counts disagree: a missing received event and an event received then filtered require different repairs.
Can IVT be stopped before an ad is served?#
Some decisions can happen before serving. Others require evidence only available during or after delivery. Pre-bid controls and post-event measurement solve related but different problems.
| Decision stage | Evidence that might be available | What the report should clarify |
|---|---|---|
| Before bidding | Inventory identity, declared supply path, historical source patterns | Opportunities evaluated and rejected, with supported scope |
| During request or rendering | Actual request context, integration behavior, event timing | Blocks versus received and measured events |
| After events accumulate | Repeated sequences, source patterns, later corroboration | Adjustments, decision time, and affected reporting interval |
These are investigation categories, not a claim that any particular vendor sees every signal. Ask each partner what it observes in your actual web, app, audio, or CTV integration.
A pre-bid rejection is an opportunity that did not become your purchased impression through that path. It should not be added to post-event invalid impressions as though the two were one population. A later invalid classification may change a previously issued report, so save export timestamps and report revisions.
Readers have asked about pre-serve versus later IVT protection and preventing suspicious native-ad traffic. The operational answer is to map available controls to their decision stages, then measure the residual exposure. No single stage establishes that all remaining events are valid.
Publisher banner protection: place the decision before the request#
A publisher asking for affordable display-banner IVT protection wants to detect suspicious visitors and avoid loading ads for them. That requires two capabilities to be evaluated separately: a useful classification and a supported control before the relevant ad request. A detector that first observes the visitor after that request cannot retroactively prevent it.
Map the actual request path before comparing products. Record when the classifier receives its inputs, returns a decision, and can influence the ad-loading code. Include any header-bidding wrapper, tag manager, fallback tag, and later refresh path that can request independently. Hiding an ad container after a request is not evidence that the request was withheld.
For a concrete implementation boundary, Google's GPT loading guide describes googletag.setConfig({ disableInitialLoad: true }). It must be configured before enabling the service and before display(). With initial load disabled, display() registers a slot without requesting its ad; a subsequent refresh() can request content for registered slots, including their first load. This is a GPT request-control mechanism, not an IVT detector, a consent decision, or a recipe covering every SSP. Confirm the complete integration and applicable demand rules with its owner.
Use a small authorized pilot before enabling a new classification rule across the site:
| Check | Evidence to request |
|---|---|
| Decision arrives in time | Classifier start/end, decision timestamp, and actual outgoing ad-request time |
| Every intended path honors it | Initial load, wrapper, fallback and refresh traces for the same slot |
| Failure has an explicit outcome | Documented timeout or unavailable-decision behavior, with that outcome logged separately |
| Legitimate visitors are reviewed | Independently assessed examples and a reversible rule, rather than the detector's score as its own proof |
| Residual delivery stays visible | Sent requests, received measurement, later exclusions and unresolved records |
A general website bot score should not be relabeled as a complete advertising GIVT/SIVT assessment without the provider's documented scope and method. Google's AdSense IVT definition includes accidental clicks as well as automated or deliberately inflated activity. A pre-request bot rule therefore cannot establish that every remaining advertising event is valid.
Hypothetical example: a publisher evaluates 1,000 defined ad opportunities and withholds requests for 60. The remaining 940 each produce one recorded request; assume the later, compatible measurement receives all 940 records and rejects 20. The gate's withheld share is 6%. The later exclusion share is about 2.13% of the 940 received records. Calling all 80 events confirmed IVT would falsely turn the 60 preliminary decisions into established invalid impressions. The 920 remaining records are simply what remains after that check, not independently verified valid traffic.
For affordability, ask which unit is billed: visits assessed, requests evaluated, measured impressions, or another defined quantity. Price the expected volume and peak load, integration work, decision latency, evidence access, and disputed-classification review together. A low subscription price with unusable coverage or substantial legitimate-user blocking may not solve the stated problem. Keep any estimate separate from measured revenue or avoided charges. If revenue changes, use the publisher request-to-revenue diagnostic before attributing the change entirely to the gate.
Why an IP blocklist is an incomplete answer#
An IP address is a network observation, not a reliable one-to-one person identifier. Google's IP address explanation notes that an ISP can assign the same address to many computers.
That creates several practical failure cases:
- Blocking a shared address can affect unrelated legitimate people.
- Changing addresses can make a static exclusion miss later activity.
- A server-side integration may expose an infrastructure address unless client context is forwarded correctly.
- A VPN label describes routing behavior; it does not independently establish an invalid advertising event.
- A hosting-provider category needs to be interpreted against the event and delivery environment.
Where supported, IP exclusions can be useful for a known internal test network. Google's exclusion documentation describes account- and campaign-level controls and their limitations. Check the current rules for your campaign type before assuming an exclusion applies everywhere.
For a suspected abusive source, combine network evidence with the event sequence, inventory identity, timestamps, and confirmed classification. Document expected collateral impact and a review date. Keep historical evidence even if the address later disappears from a list.
Before buying additional protection, evaluate Google Ads click-blocker claims or Meta-specific click-fraud tools against detection timing, supported controls, false positives, and actual billing adjustments.
For Sponsored Ads, use the Amazon gross-to-net click audit to separate its named traffic report, later revisions and account billing records.
For publisher implementations, separate browser focus from publisher refresh and viewability rules before treating a timer decision or browser state as an invalid impression.
Investigate a sudden IVT increase in this order#
1. Freeze the comparison
Choose one completed reporting window. Record campaign IDs, inventory, time zone, metric, filter settings, export time, and decision maturity. Preserve the original report before refreshing it.
Compare the numerator and denominator separately. A rate can rise because invalid volume increased, eligible volume fell, or the report started including a different population.
2. Locate the concentrated change
Break down counts by source, app or domain, creative, integration version, and hour where those dimensions are available. Retain an unknown bucket. Dropping unjoined records makes coverage look better than it is.
Rank slices by absolute invalid-event contribution as well as rate. A tiny source with a high rate and a large source with a moderate rate can require very different operational responses.
3. Separate traffic changes from measurement changes
Ask what changed around the first affected interval: acquisition source, tag deployment, player or SDK release, list version, classifier version, or reporting policy. A coincident change is a lead, not a confirmed cause.
Compare received events and classifications before and after the change. If receipt remains stable while accepted reporting falls, investigate classification and eligibility. If receipt collapses, inspect delivery and tracking before attributing the gap to IVT.
4. Review an authorized evidence sample
Request representative classified and unclassified records, plus a legitimate control cohort if available. Use access-controlled channels and redact credentials, personal data, and sensitive URL parameters.
Do not require vendors to publish detection recipes that would enable evasion. Request enough evidence for reconciliation: affected scope, decision stage, broad reason, timing, coverage, and review outcome. Escalate unresolved disputes through an agreed secure process.
5. Apply a bounded intervention
Choose a change with a measurable hypothesis. For example: pause a confirmed problematic placement while retaining a comparable placement, or repair an incorrect app identifier and verify the resulting records.
Define the observation period and success condition before the change. Preserve necessary controls, and avoid disabling filtration merely to make reports agree. Reconcile subsequent adjustments and billing separately.
Compare vendors on the same events, not just the same websites#
Two demand partners can report different IVT rates on the same publisher without measuring the same ads. They may buy different placements, win different auctions, operate at different times, or receive different tracking signals. Matching the domain name does not establish a controlled comparison.
An older publisher discussion about conflicting IVT reports raises this problem across different demand paths. The reported figures are not an independently verified test. A useful investigation needs to separate different delivery populations from different judgments about the same events.
Agree a comparable observation before comparing verdicts
Choose one completed interval and one event definition that both integrations actually support. Record the placement, format, device group, demand path, decision stage and export time. Google's discrepancy checklist similarly starts with common dates, time zones and line items. For the underlying event-path checks, use our ad-server reconciliation guide.
Where authorized and technically supported, collect two observations of the same defined events. Use documented event references and verify how retries, duplicate receipts and missing identifiers are handled. A shared IP address or nearby timestamp is not sufficient to establish that two records describe the same ad exposure. If shared event references are unavailable, ask whether the providers can perform a secured reconciliation; do not manufacture a precise join from weak identifiers.
Record four coverage buckets: usable classifications from both providers, from A only, from B only, and from neither. Here, usable means a supported, completed exclusion or non-exclusion decision for the agreed event. An unresolved or unsupported result is not a non-exclusion. One-sided coverage can reflect an unsupported environment, unavailable signals, an unclassified result, or a missing receipt. Investigate which boundary failed. Do not silently assign a missing verdict to the provider's non-excluded category.
If simultaneous measurement cannot be supported, a comparison by aligned placement, device and completed interval can still locate an aggregate pattern. Label it as an aggregate comparison. It cannot isolate classifier disagreement on identical events, and a campaign routed through another demand partner is not a substitute for that evidence.
Build a paired classification table without declaring a winner
The following example is entirely hypothetical. Assume an independent delivery ledger identifies 10,000 distinct eligible events under the agreed definition. There are 7,500 events with usable classifications from both providers, 1,500 with A only, 500 with B only, and 500 with neither. Those four buckets total 10,000. The comparison below deliberately uses only the 7,500 paired events:
| Classification on the same event | Events |
|---|---|
| A excludes; B excludes | 150 |
| A excludes; B does not exclude | 450 |
| A does not exclude; B excludes | 150 |
| Neither excludes under the compared policies | 6,750 |
| Paired total | 7,500 |
A excludes 600 of the paired events, or 8%. B excludes 300, or 4%. Their labels agree on 6,900 events, or 92% of the paired set. That is label agreement, not 92% detection accuracy. Both can miss a problem or apply the same mistaken rule. The 2,500 events without paired classifications remain outside this result; the table says nothing about their validity.
The 600 disagreements deserve investigation, but a disagreement alone does not identify which provider is wrong. Review an authorized sample from each direction of disagreement and some examples where the labels agree. Record the reference evidence, selection method, reviewer independence and uncertainty. A sample chosen only from one provider's flags cannot establish the other provider's population-wide error rate.
Ask for a case decision, then track report revisions separately
For each reviewed case, request the counted event, broad exclusion category, decision time, applicable method version, and supporting evidence the provider can disclose. Ask whether the disputed report reflects GIVT, SIVT or another exclusion, and keep unresolved cases visible. The MRC IVT addendum's discrepancy-resolution section recognizes that methods can produce different results and describes a process for reviewing instrumentation and reconciling supplied evidence. It is not a rule that the lower rate establishes the correct answer.
Keep the original export and each revision for the same service period. A classification revised on Wednesday for Monday's events is not automatically new Wednesday traffic. Nor does a revised count establish that an invoice changed. Request the affected event period, changed count, reason, and report version; separately retain any credit note, revised invoice or payment reference. The same MRC addendum addresses backward-looking assessment and correction, while the applicable agreement governs the commercial settlement. Use the delivery-to-invoice workflow to keep those records distinct.
Check the MRC listing and accreditation letter for the actual service, metric and environment when accreditation is relevant. Accreditation is not permission to treat one report as ground truth for an unverified comparison. Finish with three separate findings: coverage differences, supported classification disagreements, and unresolved or commercially disputed records. This is a diagnostic protocol, not a certification test or a vendor ranking.
Evaluate false positives without promising perfect ground truth#
A false positive is valid activity classified as invalid. A false negative is invalid activity missed by the process. Neither can be measured accurately using the classifier's own verdict as the only reference.
Use independently reviewed examples where possible. Document how reference labels were established, their uncertainty, and whether reviewers knew the original score. Include different environments, since a test set dominated by desktop browsing says little about CTV integration behavior.
A controlled legitimate session tests whether a specific integration works. It does not prove a production-wide false-positive rate. Similarly, a synthetic bot test checks known scenarios; it does not prove detection of every real scheme.
Track three outcomes for reviewed disputes: classification upheld, classification corrected, and insufficient evidence. Keep the third outcome visible rather than allocating every uncertain case to whichever side wins the commercial argument.
Prepare a scoped IVT audit-readiness packet#
An October 2026 publisher-network question about preparing for an MRC pre-audit asks whether someone can review a detailed detector methodology before the formal process. The practical gap is how to connect that methodology to the service that actually collects, filters and reports data. A long detector list cannot, by itself, demonstrate that the released implementation and customer reports follow it.
The MRC audit-process description covers annual external audits by independent CPA auditors and examines operations, data processing, technology controls, IVT filtration and disclosures. Its standards directory identifies the Minimum Standards as the foundation for assessment, alongside the applicable measurement guidance. This is broader than testing whether a particular bot pattern triggers an exclusion.
Begin with a proposed scope: service and version, reported metrics, environments, collection routes, filtration stage and the dates the evidence covers. Separate a requested scope from any accreditation already granted. The MRC digital listing and the applicable letter are the places to check a service's published scope; a preparation document should not silently extend it.
Map requirements to evidence and an accountable owner
Use the following worksheet as an editorial preparation aid, not an official MRC checklist or an assurance that a service will pass:
| Readiness area | Concrete evidence to organize |
|---|---|
| Measurement scope | Metric definitions, supported environments, counting boundaries and disclosed exclusions |
| Detection method | Documented rule or model purpose, applicable inputs, version and known limitations |
| Released implementation | Collection-to-report flow, configuration and release references, and a reproducible test record |
| Operational controls | Responsible roles, change approval, access controls and evidence of how those controls operate |
| Reporting and correction | Original report, method version, affected period, correction decision and any revised output |
| Unresolved coverage | Missing evidence, unsupported cases, responsible owner and the next verification step |
The currently linked Minimum Standards address operational integrity, disclosures and electronic-delivery controls. Check applicability with the responsible audit team rather than copying a retention period or survey requirement into every digital integration. The worksheet organizes the conversation; it does not replace those standards or an auditor's requested evidence.
Trace one result from input through correction
For an authorized test, follow a defined observation through collection, normalization, filtration and the report. Retain the relevant method/configuration version and identify which exclusions overlap. A test that confirms one detector fired does not establish that the final numerator, denominator or customer-facing explanation is correct.
Hypothetical example: a controlled test exposes a classification error after a release. A useful readiness record links the test evidence, affected implementation, decision owner, bounded affected reporting period and the revised output. If the affected population cannot yet be established, record that uncertainty. Neither fixing the detector nor issuing a revised report proves that every historical result was corrected.
Keep independently reviewed legitimate and invalid examples separate from the detector's own labels. Use the false-positive review guidance above, and preserve unsupported outcomes. Share sensitive raw evidence only through an agreed, access-controlled process; a public runbook does not need visitor identifiers or proprietary detection recipes.
Finally, keep readiness, audit participation and accreditation separate. MRC explicitly states that services under review are not accredited. An internal review, consultant assessment or completed test therefore should not be presented as an accreditation decision. Close each preparation item with its verified evidence and remaining gap, rather than inventing a readiness percentage or claiming that a larger manual establishes better detection.
Copy this evidence request to your provider#
Subject: IVT reconciliation request for [campaign / interval]

Event and scope:
Campaign, source, placement, creative, environment:
Start/end and time zone:
Original export and subsequent export times:
Counting event definition:

Counts:
Received requests:
Eligible measured events:
GIVT exclusions, deduplicated:
SIVT exclusions, deduplicated:
Other exclusions:
Unclassified / unsupported:
Accepted report count:

Method and coverage:
Exact numerator and denominator for each rate:
Census, random sample, or risk-selected review:
Pre-serve blocks versus post-event exclusions:
Overlapping reason-code treatment:
Classification and list/model version where shareable:

Review:
Affected slices and change onset:
Representative event references through secure channel:
Alternative legitimate explanations considered:
Review owner, expected response, and report revision policy:
Billing adjustment reference, if applicable:
For mobile-app interactions, audit high AdMob CTR and accidental-tap timing. Accidental clicks can create invalid-traffic concerns even when no deliberate fraud has been established. For a publisher account notice, separate AdSense account review from traffic classification; the notice itself does not identify which individual visits were invalid.
Frequently asked questions#
Is invalid traffic the same as advertising fraud?
No. IVT can include accidental or otherwise nonqualifying activity. A classification establishes a measurement result under stated rules; proving deliberate deception requires further evidence.
If 500 of 10,000 events are invalid, is the IVT rate 5%?
It is a 5% detected-invalid share if the numerator is 500 distinct invalid events and the denominator is the same 10,000 eligible events. If only a selected subset was assessed, disclose that limitation. Do not assume the rest were verified valid.
Does a low IVT rate prove traffic quality?
No. The rate depends on coverage, event definitions, and detection capability. It does not independently establish viewability, correct targeting, attention, or business outcomes. Read the campaign delivery verification guide for those separate checks.
Should every VPN or automated request be called fraud?
No. Network routing and automation need contextual classification. Legitimate tools may generate activity that should be excluded from audience measurement without implying malicious intent. Preserve the distinction between a technical exclusion and an accusation.
Can I compare two vendors by their reported IVT percentages?
Only after aligning event populations, coverage, reporting time, decision maturity, and exclusion definitions. When two partners buy different ads on the same website, their rates are not a matched-event test. Use the paired comparison workflow where supported; label agreement still does not establish detection accuracy.
Does a later IVT report revision prove a billing correction happened?
No. Preserve the original and revised classifications for the same event period, then request the separate commercial adjustment record. A changed count, a requested credit and a completed payment correction are different statuses; the applicable agreement determines their relationship.
Put evidence before the percentage#
The useful IVT report lets you explain which events were evaluated, which were excluded, and which remain uncertain. Build that ledger before changing source budgets or disputing invoices.
Explore AdProof's measurement approach, review verification solutions, or discuss a campaign reconciliation with the event definitions and evidence above. Confirm the required measurement coverage for your own integration before selecting a workflow.
Sources and research notes#
Initial research: 25 October 2026. Publisher pre-request controls checked on 26 October 2026; matched-event vendor comparison sources checked for this proposed update on 28 October 2026. Primary references are the MRC standards directory, its 2020 IVT addendum, the 2024 interim update, and the Google definitions and controls linked beside the relevant claims. Forum discussions supply reader questions, not validated diagnoses. All worked figures are hypothetical, and the investigation templates are editorial recommendations rather than claims of accreditation or product capability.
Understand the denominator behind your IVT rate.
Compare received, eligible, invalid and accepted counts before interpreting a percentage.
Discuss traffic measurementA measurement discussion, with scope confirmed before any next step.