
- Published
- Oct 30, 2026
- Reading time
- 11 min read
ChatGPT Ads Measurement: What to Ask for Before Buying
Build an evidence checklist for ChatGPT ads: reporting scope, contextual controls, landing-page checks, attribution and the limits of placement evidence.
In this guide (10 sections)
Before buying conversational advertising, obtain a sample export, a written explanation of the available contextual controls, and a reporting definition for the decision you intend to make. Separate evidence of delivery, evidence about surrounding context, website activity and business outcomes. A satisfactory report in one category does not answer the others.
This is a practical buying question, not a request for access to private conversations. An ad-operations discussion about placement reports for AI advertising asks what buyers should request before committing budget. The underlying concern is useful: a familiar placement-report workflow may not transfer to a conversational surface. The thread's broader assertion that placement reporting is absent everywhere is not established evidence about every platform or account.
This guide uses current ChatGPT Ads documentation as a concrete example, checked on 30 October 2026. The audit steps are recommendations; they are not a claim that every field or control below is available in Ads Manager.
Define what you mean by a placement#
A platform name, an ad unit, a generated answer, an adjacent topic and an individual exposure are different reporting objects. Calling each one a placement makes a procurement discussion sound resolved when it is not.
Write the actual question in the media brief:
- Which product surface or environment delivered the ad?
- Which aggregate contextual categories, if any, can be reported?
- Which restrictions were applicable and active?
- Can a specific reported incident be investigated through an authorized process?
- Which outcomes can be compared after arrival on the advertiser's site?
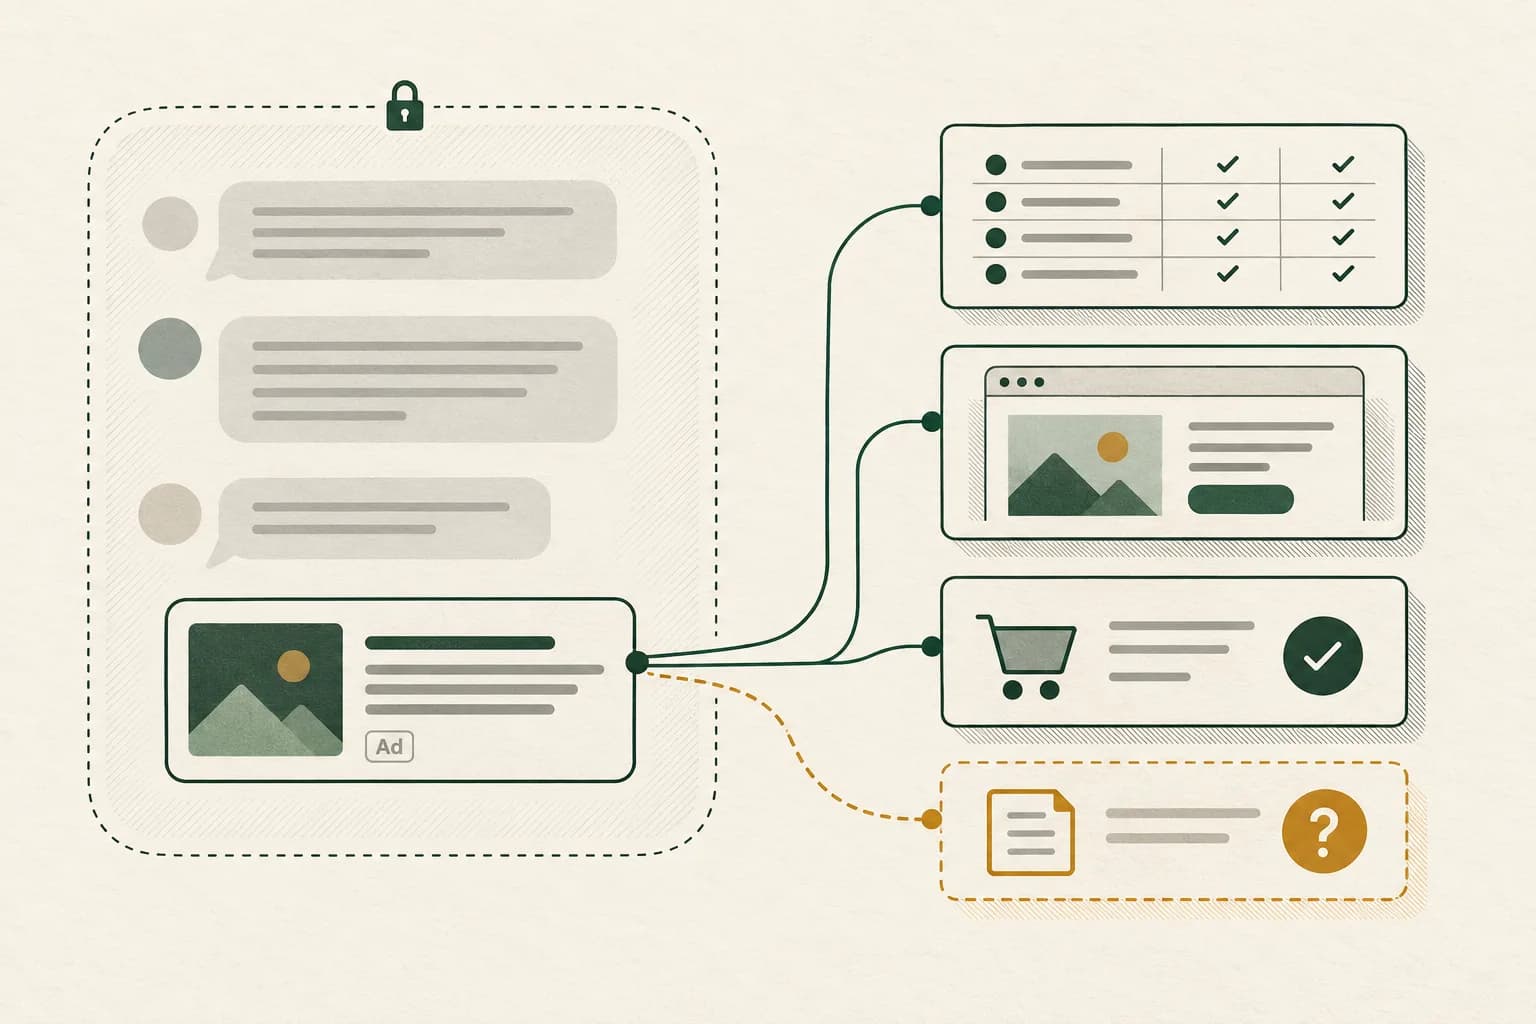
Ask the seller which of these it can answer, at what granularity, and with what limitations. An illustrative screenshot shows a possible layout; it is not a log of all delivered contexts. A context instruction records intended relevance; it is not a receipt establishing what every exposure accompanied.
For ChatGPT specifically, OpenAI documents ads below responses and says advertiser context hints guide relevance without guaranteeing particular conversations. Negative Phrases are limited to qualifying advertisers. Treat eligibility and control scope as questions for the actual account. OpenAI's advertiser basics
Set the reporting contract before a test
Delivery, context, website activity and business outcomes need separate evidence. Discuss what reporting is supported for your intended decision.
Discuss a measurement questionA short inquiry to scope relevant options; no campaign access is needed.
Keep the privacy boundary in the evidence plan#
OpenAI says advertisers receive aggregate, non-identifying performance information, not users' chats, chat history or memories. It also distinguishes paid ads from independent answers. OpenAI's ads FAQ
Design the audit around permitted evidence. Do not request raw conversations, reconstruct them from landing-page identifiers, or turn a URL parameter into a claim about a person's private question. Ask whether aggregate category reporting, controlled demonstrations, documented controls or an incident-review procedure can answer the business requirement.
If procurement requires proof of the precise adjacent content for every impression and the available product cannot supply it, record that mismatch before purchase. A smaller test budget does not waive a mandatory policy. Conversely, a team allowed to buy using aggregate evidence can document that choice without pretending it has impression-level contextual verification.
Use the brand-safety and suitability workflow to define the policy first. The additional task here is translating that policy into evidence a conversational product can actually provide.
Build an evidence contract before the first test#
Use this table as a request sheet. The rightmost column describes a recommendation for your review, not a list of platform features.
| Decision | Evidence to request | How to handle an unavailable answer |
|---|---|---|
| Confirm purchased delivery | Sample report, metric definitions, IDs, dates and billing basis | Resolve the measurement ambiguity before comparing rates |
| Assess contextual suitability | Applicable policy, control scope, available aggregate context evidence and incident process | Record unknown context separately from acceptable or unacceptable context |
| Check landing-page arrival | Approved tracking settings, redirect test and permitted site observations | Assign a tracking owner and retain the unobserved gap |
| Evaluate business quality | Defined outcome, validation rule and comparison population | Keep submissions separate from qualified leads or completed orders |
| Decide whether to scale | Pre-agreed decision rule, reporting maturity and investigation results | Extend investigation or stop according to the original rule |
Name the person responsible for each answer. The buyer owns the purchase decision; the implementation owner checks the landing path; the analytics owner defines outcomes; the policy owner accepts or rejects the remaining contextual uncertainty.
Save a dated copy. A later report expansion should create a new evidence version rather than silently changing what the initial test was considered capable of proving.
Obtain a real export and preserve its scope#
OpenAI documents campaign, ad-group and ad reporting, CSV exports and Device, Country and Platform segmentation. Delivery figures typically refresh around 15 minutes, spend later, and attributed conversions can take 24–48 hours. Save the reporting snapshot and its maturity. Measure Results
Those documented breakdowns do not establish the existence or absence of a conversation-level placement report. Check the actual account and obtain clarification about any additional reporting offered.
For your own comparison record, retain the account, campaign and ad IDs, selected dates, timezone, export time, exact columns, filters and active settings. Preserve both the original CSV and the worksheet used to interpret it. A renamed column should not erase the historical definition.
Use daily rows for a time trend and a consistent cumulative scope for totals. Before joining files, confirm whether a row represents a campaign, an ad, a day or a segmented combination. Summing a campaign total together with its constituent rows counts the same activity twice.
Do not convert an empty or unsupported category into a zero. Mark whether evidence is absent, withheld, pending or outside the report's scope. Those conditions imply different next actions.
Test the path from ad configuration to website activity#
Start with a controlled landing-page test. Keep the destination, redirect behavior, approved parameters, consent state and measurement configuration in the test record. A successful browser navigation establishes that tested path; it does not validate every future paid exposure.
OpenAI documents static UTM tracking and warns that ad-review crawler visits can appear in third-party analytics without being billable clicks. Its reporting documentation also supports dynamic URL parameters. Choose supported settings, then verify their behavior rather than assuming a paid-looking source label proves a paid click. Tracking basics, reporting reference
Check one change at a time: redirect preservation, destination loading, consent handling, analytics firing and the intended outcome. Preserve authorized technical evidence with sensitive values removed. Separate test traffic from the evaluation period wherever your tools support it.
If click and session totals disagree, investigate the arrival path before making a claim about media quality. A session depends on its own collection rules; a landing request is another event. The platform-versus-independent measurement guide provides a reusable comparison contract for these differences.
Verify conversion definitions before reading the result#
Decide whether the business question concerns submitted forms, accepted leads, orders or another action. Record the selected event and date basis. Do not treat a sum of different event types as a unique-customer count.
There is a current documentation discrepancy worth retaining: Measure Results describes eligible view-through conversions inside the total when enabled; the developer Pixel attribution reference describes them separately, excluded from Conversions. Verify the account's columns and windows and obtain clarification before reconciling totals. Do not assume one universal definition from the label alone.
Save the actual export and the definition used for that run. A later clarification should annotate the interpretation, not overwrite the original observation. If a conversion is missing, distinguish an absent outcome, an unreceived measurement event, an attribution difference and incomplete reporting maturity before changing campaign settings.
For outcome quality, compare a consistently defined business status with the relevant platform metric. A sales team rejecting a lead is evidence about that lead's recorded qualification; it does not retroactively establish that the preceding impression or click was invalid.
A worked example: three questions, three denominators#
Hypothetical example only. An advertiser exports a sufficiently mature test period in one timezone. It records 50,000 reported impressions, 500 reported clicks and spend of 1,000 currency units. Its site analytics records 420 sessions under the agreed campaign tagging, while its business system records 30 accepted leads in the separately defined site-acquisition cohort.
| Calculation | Result | Proper interpretation |
|---|---|---|
| Reported clicks / reported impressions | 500 / 50,000 = 1% | Reported CTR for that delivery scope |
| Reported spend / reported clicks | 1,000 / 500 = 2 | Cost per reported click in the same scope |
| Tagged sessions / reported clicks | 420 / 500 = 84% | A diagnostic ratio across two measurement systems |
| Accepted leads / tagged sessions | 30 / 420 ≈ 7.14% | Observed cohort yield under the chosen site definitions |
The 80-count difference between clicks and sessions is not automatically 80 people lost, fraudulent clicks or refundable charges. Repeated interactions, collection and cohort differences require investigation. Nor do the 30 leads establish incremental lift: the example has no counterfactual.
Now suppose the buyer has no delivered contextual-category report for this period. That remains an evidence gap. Strong lead yield cannot fill it, and the absence of that report does not itself prove unsafe adjacency. The policy owner must decide whether the documented controls and available review process satisfy the requirement.
Make scaling a decision, not a dashboard reaction#
Write the test's evaluation rule before viewing results. Specify the permissible spend, required policy evidence, minimum useful business information, reporting maturity and investigation triggers. These are buyer choices, not universal thresholds.
Keep contextual acceptance separate from performance acceptance. A campaign might satisfy the first and fail the second, or produce attractive outcomes while leaving a mandatory contextual requirement unresolved. Record both conclusions.
If the decision requires incremental impact, involve an analyst in a controlled evaluation with a credible comparison, adequate sample and pre-specified outcome. A convenient geographic split or before-and-after comparison can differ for reasons unrelated to advertising. Record assignment, contamination, seasonality and uncertainty; do not rename attributed conversions or a favorable split as proven causal lift.
Use a change log for creative, landing pages, targeting, tracking and reporting configuration. A test that changes all five at once may still provide operational learning, but it becomes harder to explain which change accompanied the outcome.
Turn an unresolved gap into a useful escalation#
An effective support request contains a reproducible question rather than a demand that every system agree. Provide permitted account and campaign references, exact report scope, extraction times, column definitions, settings and sanitized evidence of the specific discrepancy.
Ask for a precise response: Is the requested dimension supported? What population does the column count? Which configuration applied at the event time? Can the incident be reviewed without disclosing private conversation content? What evidence would distinguish a delivery problem from a reporting limitation?
Track the answer as confirmed, contradicted or unresolved. Preserve the limitation if it remains unresolved; do not manufacture a category or classify every unknown exposure as safe to complete the spreadsheet.
For supported campaigns already measured in AdProof, use a campaign/date/timezone-scoped export to review available delivery records and permitted device or country slices. Keep that evidence separate from ChatGPT's own reports. The fashion-retail delivery-quality case illustrates a separate quality-review workflow; it is not evidence of a ChatGPT integration. Discuss your available evidence with AdProof before assuming a new buying surface can be independently measured.
Frequently asked questions#
Should I refuse a conversational-ad test without a placement report?
Base that decision on the evidence your approved policy requires. Resolve mandatory gaps before purchase. Where an aggregate-evidence test is permitted, record the limitation, budget and review conditions explicitly.
Does a good conversion rate establish safe surrounding content?
No. Outcome quality and contextual acceptability answer different questions. Evaluate each against its own evidence and approval rule; a strong result in one cannot supply missing observations in the other.
Can I use website tracking to reconstruct the conversation around an ad?
Do not design the audit that way. Use permitted delivery and site evidence for their declared purposes, and request privacy-preserving contextual assurance through the platform's supported process.
What should the first test produce before we scale?
A reproducible report package, a checked landing path, clearly defined outcomes, a documented contextual decision and a list of unresolved issues with owners. Retain enough evidence for another reviewer to understand exactly what the test established.
Set the reporting contract before a test
Delivery, context, website activity and business outcomes need separate evidence. Discuss what reporting is supported for your intended decision.
Discuss a measurement questionA short inquiry to scope relevant options; no campaign access is needed.