
- Published
- Nov 5, 2026
- Updated
- Nov 18, 2026
- Reading time
- 17 min read
GA4 Missing Report Rows: Thresholds, Sampling and (other)
Diagnose missing GA4 report rows by separating privacy thresholds, sampling, grouped (other) values, filters and pagination before changing your tracking.
In this guide (12 sections)
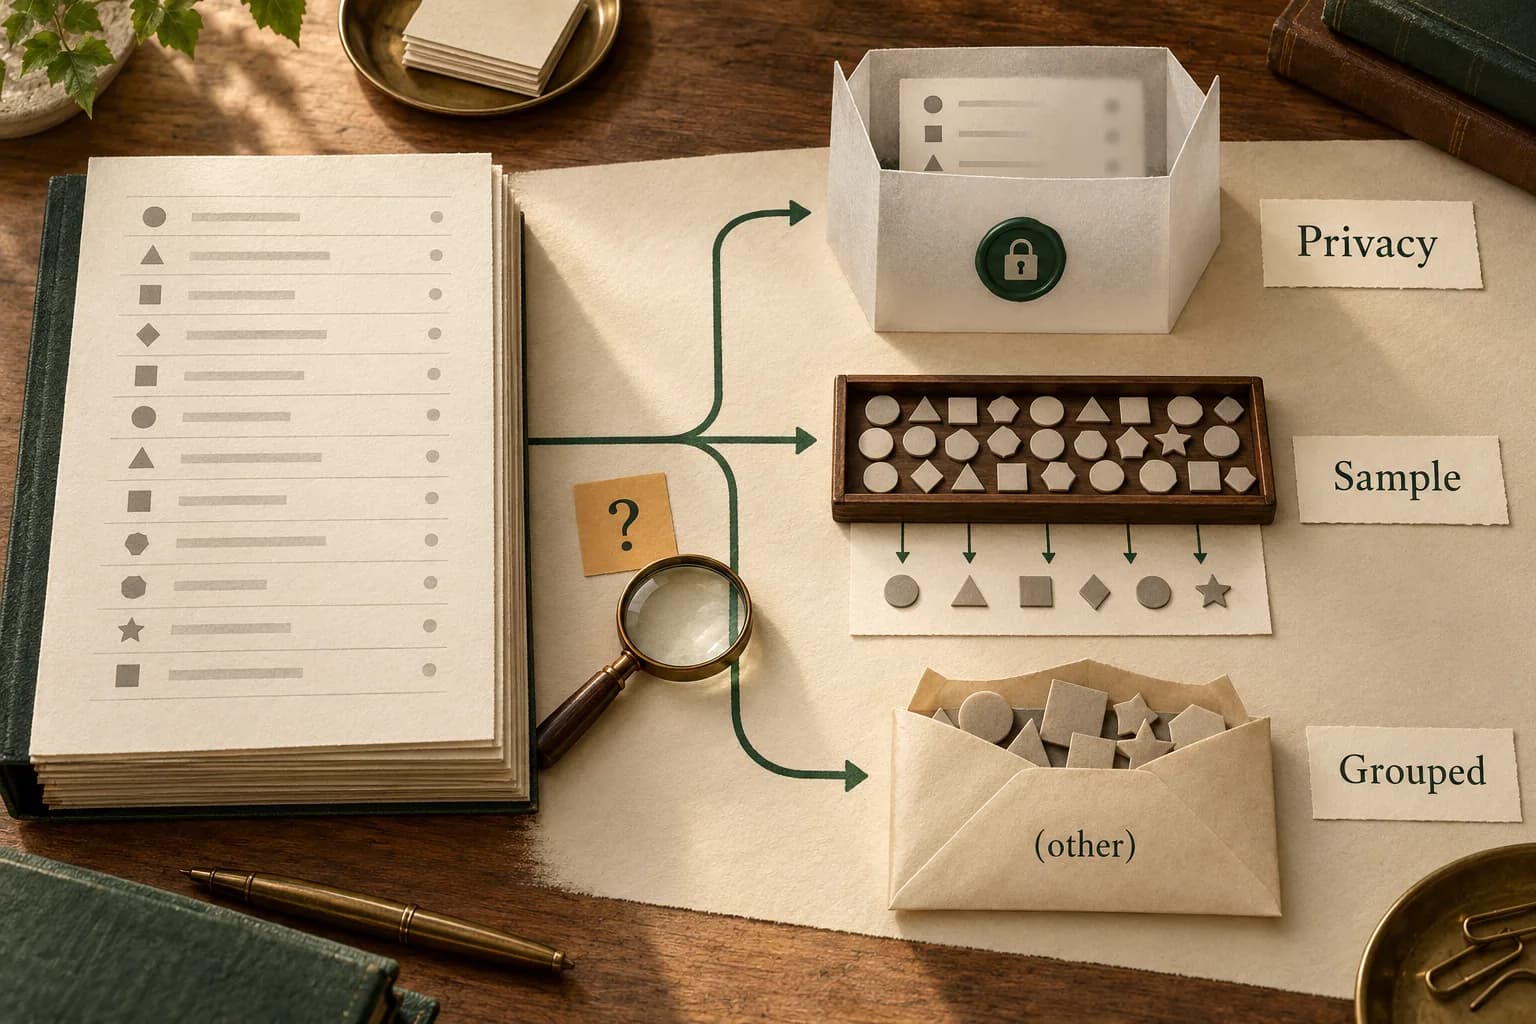
When a GA4 chart contains activity but its table loses rows, first inspect that report's data-quality message and exact query. Privacy thresholds can withhold data, sampling estimates results from a subset, and high-cardinality combinations can be grouped into (other). Filters, pagination, scope and processing maturity introduce separate differences. None of these symptoms alone proves that the tracking tag stopped collecting events.
Save the original report before changing settings. A correction that makes two totals match is useful only if the revised report still answers the business question.
Why an older answer may solve the wrong problem#
In an older sampling-and-thresholding discussion, a practitioner asks how to deal with gaps and inconsistent reporting. A separate page-level conversion question reports different totals after adding Page path. These are genuine, older questions, not evidence of a new GA4 outage.
The Stack Overflow question about pageviews appearing in a graph but not a table dates to June 2023. Its answer proposes a fixed approximate privacy cutoff and a reporting-identity change. Treat those as historical suggestions, not a universal current diagnosis. Read the messages and definitions exposed for your actual report.
If no events arrive anywhere, follow the GA4 receiving-path investigation. If rows exist but the dimension value is (not set), use the missing landing-page and attribution guide. This guide addresses activity whose presentation or breakdown changes when you query it.
Separate missing rows from a failed request.
If a request fails, diagnose its quota and scheduling boundary before interpreting a missing result.
Read the Data API quota diagnosticOpens a practical guide. No email required.
Start with a report contract#
Capture the following in one worksheet:
| Item | What to record |
|---|---|
| Source | Property, data stream where relevant, reporting surface and access role |
| Time | Explicit start/end dates, property time zone and retrieval timestamp |
| Measure | Exact metric, aggregation and counting scope |
| Breakdown | Every dimension, including secondary or connector-added dimensions |
| Selection | Filters, comparisons, segments and inclusion/exclusion conditions |
| Processing | Data-quality text, sampled percentage and data maturity |
| Extraction | Visible rows, exported rows, pagination and connector limits |
| Identity | Reporting identity used when each result was obtained |
“Same date range” is not enough when one table uses Page title and another uses Page location. Two pages can share a title; one page can acquire many URL variants. Write down the dimensions instead of treating their labels as interchangeable.
Google's reporting-data expectations explains that adding dimensions can change which events are eligible for a report. It also notes that UI and API reports use the property's reporting identity. A settings change between extractions can therefore invalidate the comparison even when the dates match.
Classify the mechanism before choosing a remedy#
| Observation | Mechanism to test | First diagnostic move |
|---|---|---|
| A threshold message accompanies a small demographic or query segment | Privacy thresholds | Reproduce without the sensitive breakdown, retaining the original |
| The quality indicator reports a sampled percentage | Sampling | Save the percentage and test a smaller, comparable query |
(other) appears, or its warning remains after filtering | Aggregated dimension combinations | Remove unnecessary breakdowns and inspect grouping metadata |
| Export stops after a consistent number of rows | Pagination or connector extraction | Compare returned rows with the result's row count |
| A simpler report contains more activity without a quality warning | Query shape, filters or scope | Add one dimension or condition at a time |
| Recent dates change between downloads | Processing maturity | Repeat the identical query after the relevant processing window |
Several mechanisms can coexist. Keep a finding marked unconfirmed until the observed message or a controlled comparison supports it.
Privacy thresholds: withheld data is not zero#
Google's current threshold guidance describes protection against identifying individuals from sensitive reporting information. Demographics and search-query reporting are examples. The thresholds are system-defined, and the quality indicator identifies affected reports or cards. A broader date range may make a previously small aggregate reportable.
Do not infer a universal rule such as “every row below 30 sessions disappears.” The missing-row count, metric and relevant privacy conditions are not established by a number copied from an old answer.
For diagnosis, compare the same metric with and without the sensitive breakdown. Label this as a different query. If the wider result is usable, answer the question at that permitted aggregate level. Do not substitute zeros for withheld rows or distribute a residual total among individuals.
A change in reporting identity is also a change in the measurement basis, not merely a button to reveal hidden cells. Preserve the original setting, obtain the appropriate approval for any account change, and document what the revised report represents. A device-based report that happens to match another total does not prove the previous identity method or consent implementation was defective.
Sampling: a subset used for estimation#
Sampling uses part of the eligible data to estimate a larger result. GA4 exposes the percentage used through the data-quality indicator when sampling applies. It is different from suppressing specific low-volume rows for privacy.
Try an intentionally smaller query while retaining the metric and necessary dimensions. A shorter interval may reduce the event volume involved, but record the new interval as a separate test. Do not assume every filter reduces sampling: the underlying processing path matters.
Avoid dividing an already estimated result by the sample fraction again. Also avoid treating a nonsampled report as an exact census of people. Unique-user and session measures can involve approximation and identity rules separately from event sampling.
For a longer business period, do not casually add daily user counts after splitting requests. Someone active on several days can appear in several daily rows. The same issue can arise across overlapping segments. Choose an aggregation that preserves the intended unique population rather than repairing a sampling warning with double-counting.
(other): grouped values, not a missing field
Google's (other) documentation describes less-common dimension combinations being condensed when an underlying table reaches its row limit. Multiple dimensions increase the combinations needed. The often-cited 500-value cardinality guidance is not a universal report-row cap.
An (other) group is also different from (not set). The former can contain recorded values whose detail is grouped; the latter indicates unavailable information for the selected dimension. Renaming either to Direct or Unknown in a spreadsheet destroys that distinction.
Start by removing a secondary dimension that the decision does not require. Compare Page path with a URL field containing many query-string variants only if the changed question is acceptable. For future instrumentation, avoid registering unnecessary per-event or per-person identifiers as custom dimensions. Keep the business need for the detail explicit; do not strip parameters indiscriminately when they distinguish meaningful content.
A filter can hide the displayed (other) row without recovering its components. A warning therefore matters even if no visible row carries that label. You have changed what is shown, not necessarily reconstructed the detailed population.
API and connector checks that expose extraction problems#
When an authorized analyst uses the Data API, retain the response metadata alongside the rows. A connector that hides it may require a bounded support request. Do not assume that calling an API bypasses UI reporting rules.
The ResponseMetaData reference provides useful distinctions:
| Response field | How to use it |
|---|---|
subjectToThresholding | The request is subject to thresholds; true does not prove that any row was withheld |
dataLossFromOtherRow | Dimension combinations were grouped in the underlying aggregate table, even if a filter removes (other) from this view |
samplingMetadatas | Sampling information for the requested date ranges when results are sampled |
emptyReason | A stated reason for an empty result, when supplied |
dataTruncationReasons | Explicit truncation information, when supplied |
schemaRestrictionResponse | Access-related metric restrictions to investigate separately |
Save the request as well. A metadata flag describes that result, not every report the property has ever produced.
Google's pagination guide explains that rowCount represents query-result rows independently of limit and offset. Compare it with the rows actually fetched. Page through the same request shape, keeping dates, dimensions, filters and ordering consistent. Increasing the page size cannot unfold values already grouped by the reporting table.
Worked example: three different gaps#
The following numbers are hypothetical and use event counts, not unique users. They illustrate diagnosis, not expected GA4 behavior or an actual property result.
A simplified report for one settled interval contains 30,000 eligible events. Its mutually exclusive dimension rows are:
| Displayed group | Event count |
|---|---|
| Page group A | 18,000 |
| Page group B | 7,000 |
(other) | 5,000 |
| Total | 30,000 |
An analyst exports A and B and calls their 25,000-event sum “all events.” The 5,000-event gap is explained by an omitted grouped row in this constructed example: 18,000 + 7,000 + 5,000 = 30,000. It does not show 5,000 lost network requests, fraudulent visits or thresholded people.
Filtering for a page believed to sit inside (other) is not guaranteed to reveal its event count. Google's API expectations notes that filters do not inspect the contents of that group. A separate query strategy or appropriately scoped export investigation is needed; allocating the 5,000 proportionately would be an estimate invented by the analyst.
Now suppose a different export reports rowCount: 24000, but the client saved 10,000 rows. That is a 14,000-row extraction gap, not automatically 14,000 events. Each row can contain a different event count. Complete pagination before diagnosing collection loss.
Finally, suppose a demographic comparison is subject to privacy thresholds. That describes a third query. Neither the 5,000 grouped events nor the 14,000 unfetched rows proves how much information the demographic query withheld. Keep three separate findings instead of adding unrelated gaps together.
Decide when a recent report is usable#
A retained Stack Overflow question from 25 October 2022 asks how to schedule a prior-day management report when the API settles at different times. It remains a useful operational question; its age is explicit, and the accessible page contains no answer. A separate GA4 reporting-delay discussion compares GA4 with Clarity. Those observations do not establish a current platform incident or equivalent visit counters.
The immediate action is to distinguish available, acceptable for a named decision and permanently final. A query can succeed while its recent results are still changing. A manager may accept a labeled provisional event total while postponing channel-credit conclusions. Write that acceptance rule before selecting a convenient extraction time.
Google's freshness guidance gives typical prior-day availability times in the property's timezone, explicitly without a timing guarantee. Processing may take 24–48 hours; daily data and API queries can still change, and key-event attribution credit may change for up to 12 days. The same guidance describes stricter intraday cardinality limits and temporary event-scoped traffic-source gaps. Do not turn a typical timetable into an account-specific readiness guarantee.
Use a readiness record, not a made-up final flag
The current runReport reference and response metadata contract do not document a universal “this day is now final” field for this workflow. A missing quality warning is not that signal. Likewise, the appearance of a BigQuery daily table does not prove that the API report has finished every processing or attribution step.
Use the following as an analyst-defined release protocol, not a Google-provided completion detector:
| Readiness record | Decision it supports |
|---|---|
| Fixed query definition | Confirms the second extraction asks the first extraction's question |
| Property date and timezone | Makes the age of the selected day interpretable |
| Retrieval timestamp | Separates reporting-date age from the time the report was requested |
| HTTP outcome and saved rows | Distinguishes unavailable output from a returned zero |
| Extraction completeness | Confirms pagination was completed for that query |
| Quality metadata | Retains sampling, grouping, threshold and restriction evidence |
| Prior matching snapshot | Enables a measured change calculation without overwriting history |
| Business acceptance rule | Identifies who may use the result, for which decision and with what caveat |
Fingerprint the logical query, including dates, dimensions, metrics, filters and relevant identity context. Keep pagination offsets in the extraction manifest, separately from that logical definition. A different page offset is part of retrieving one result; a changed dimension is a different report. Repeated requests that accidentally change either boundary cannot demonstrate stability.
Set a bounded retry policy with the integration owner. Retry later according to the decision's deadline and observed processing, rather than refreshing every chart continuously. If the required result remains unavailable at the deadline, publish its unavailable/provisional state and last successful timestamp. Do not silently carry yesterday's number under today's label. The quota investigation covers workload failures separately from maturation.
Worked example: stable enough for one decision
Hypothetical example: three identical queries for one property-local day return 9,000, 10,000 and 10,050 eligible events at successive observation times. The second-to-third change is 50 events, or 0.5% of the second snapshot: (10,050 - 10,000) / 10,000 × 100. This is not a measured GA4 account result or a proposed universal tolerance.
Suppose the reporting owner has explicitly accepted a provisional event-volume estimate within a 1% snapshot-change rule for an internal morning note. The third snapshot satisfies that particular comparison. It does not prove no events will arrive later, settle source attribution or permit an invoice adjustment. If the first comparison used users rather than events, its population and interpretation would need their own definition.
Keep both snapshots, the elapsed time and the actual rule. Two unchanged requests made seconds apart provide different evidence from two unchanged observations separated by a meaningful processing interval. Even the latter establishes observed stability only over those observations. Future changes remain possible.
For a channel-credit decision, repeat the channel-level comparison rather than accepting a stable overall event total as evidence that the channel split is settled. A report can keep the same total while reallocating credit between rows. Do not sum daily unique users to repair a changing full-period result, or allocate an unexplained difference among channels.
When an app report is far below the BigQuery event export
A Google Analytics Community question titled “Almost all app data missing in GA4 for 13 November, but available in BigQuery” reported a property-specific discrepancy for Android and iOS across countries. The author described roughly 1.3 million BigQuery events versus around 19,000 events in reports or Explorations, with web data and nearby dates appearing more normal. The page shows a recommended answer accepted by the author, dated Nov 16, 2026 at 9:37 AM; the timezone is not specified in the visible timestamp. The answer attributes the symptom to a processing delay and recommends waiting when the low date is isolated and realtime users are present. This is a community response for one report, not an official incident notice, a general resolution guarantee, or proof that every property with a gap has the same cause.
For a comparable investigation, first align the population. BigQuery's GA4 export contains raw event data; Google says those exported events can differ from the Analytics interface because reports include value additions and use report-specific processing. Compare the same property and app stream, event names, date, registered timezone, filters and dimension scope. Keep event rows, sessions and users as separate units.
Then check which export table is being queried. Daily tables are named events_YYYYMMDD; streaming tables use events_intraday_YYYYMMDD and are replaced after the daily table is complete. Do not add both sets for the same date unless the query has an explicit, verified deduplication rule. Google documents that daily event tables can receive late-arriving updates for up to three days; its freshness guide says report data can change during processing and that common processing may take 24–48 hours, with timing not guaranteed.
Use a controlled comparison:
- Save the exact GA4 report or Exploration definition, property timezone, app stream, date, event name, dimensions, filters and any data-quality message.
- Save the BigQuery table name and query, including whether it reads a daily or intraday table and whether it combines both.
- Count matching event names and compare a small redacted sample of event timestamps and parameters. Do not compare a total event row count with a report's user or session metric.
- Repeat the same report after its processing window and check whether the same date changed; retain both retrieval times.
- If the discrepancy remains, document the precise query and stream scope before investigating collection or contacting support.
Hypothetical arithmetic: a query returning 1.3 million event rows and a report returning 19,000 event counts differ by 1,281,000 in those displayed units. That subtraction does not measure missing users, sessions, purchases, or ad-attributed outcomes. A report may be filtered, dimensioned, processed differently, or represent another unit. State the metric and denominator before estimating impact.
Do not disable event collection, rewrite app instrumentation, or promise reprocessing just to force two surfaces to agree. BigQuery is a distinct exported dataset with its own schema, limits and processing boundaries; it is not a universal substitute for report definitions or attribution. Link to the existing BigQuery export limits and streaming completeness guide for export timing and schema details.
Retention and collection remain separate checks#
A historical retention issue needs its own investigation. Read any explicit truncation reason, check which surface and period it affects, and distinguish stored aggregate reports from the data available for a detailed analysis. A recent live event test cannot establish that an old report still has every required field.
Likewise, an active incoming-data filter differs from a report filter: collection or processing exclusions may remove data that a reporting toggle cannot restore. The collection guide covers that boundary. Keep the tracking QA checklist for implementation tests after the evidence points there.
Close the investigation with a usable reporting contract#
Your final record should state the original question, query, observed limitation, corrective query or extraction, remaining unknowns and accepted counting basis. Preserve both results. Do not overwrite the original report with a cleaner-looking number and lose the explanation.
For ad-delivery reconciliation, use AdProof's supported campaign, time-zone, placement and event/report exports to build a separate evidence scope. Our anonymized food-and-spices gaming review illustrates why findings stay attached to selected placements. It is not a GA4 thresholding case or proof of equivalent counts across products.
Discuss a scoped measurement review with the report contract and the first unresolved handoff. AdProof does not recover GA4's withheld rows, rebuild its reporting identity or remove its reporting limits. The useful workflow is to preserve each system's population and compare measurement definitions before drawing a campaign conclusion.
Frequently asked questions#
Is an unchanged API response proof that the day is final?
No. It shows stability between those observations for the same query. Keep a decision-specific provisional acceptance rule, the observation interval and the metadata. The current reporting references do not provide a universal final-day flag for this workflow.
Is every missing GA4 row caused by thresholding?
No. Check the exact quality message, filters, requested dimensions, pagination, processing maturity and scope. Grouping into (other), sampled estimation and incomplete extraction need different remedies.
Does a true subjectToThresholding flag prove data was hidden?
No. Google's metadata contract says the request can be subject to thresholds while all its data meets them. Save the flag and query, then investigate the specific comparison rather than estimating an omitted count from the flag alone.
Can exporting the same report through the API recover every row?
No. The Data API can return sampled, thresholded or grouped results. Complete pagination for rows that exist in that query, but do not confuse unfetched rows with values already condensed into (other).
Should I shorten or expand the date range?
It depends on the observed mechanism. A smaller query may reduce sampling or cardinality pressure; a broader permitted aggregate may reduce privacy suppression. These are different diagnostic tests, and summing unique-user counts from split periods can double-count people.
Separate missing rows from a failed request.
If a request fails, diagnose its quota and scheduling boundary before interpreting a missing result.
Read the Data API quota diagnosticOpens a practical guide. No email required.