
- Published
- Oct 31, 2026
- Reading time
- 10 min read
Prebid Highest Bid vs Rendered Ad: Trace the Selection
Diagnose Prebid bid-to-render mismatches with frozen auction evidence, adjusted CPM, selection policy, bid identifiers and separate render receipts.
In this guide (10 sections)
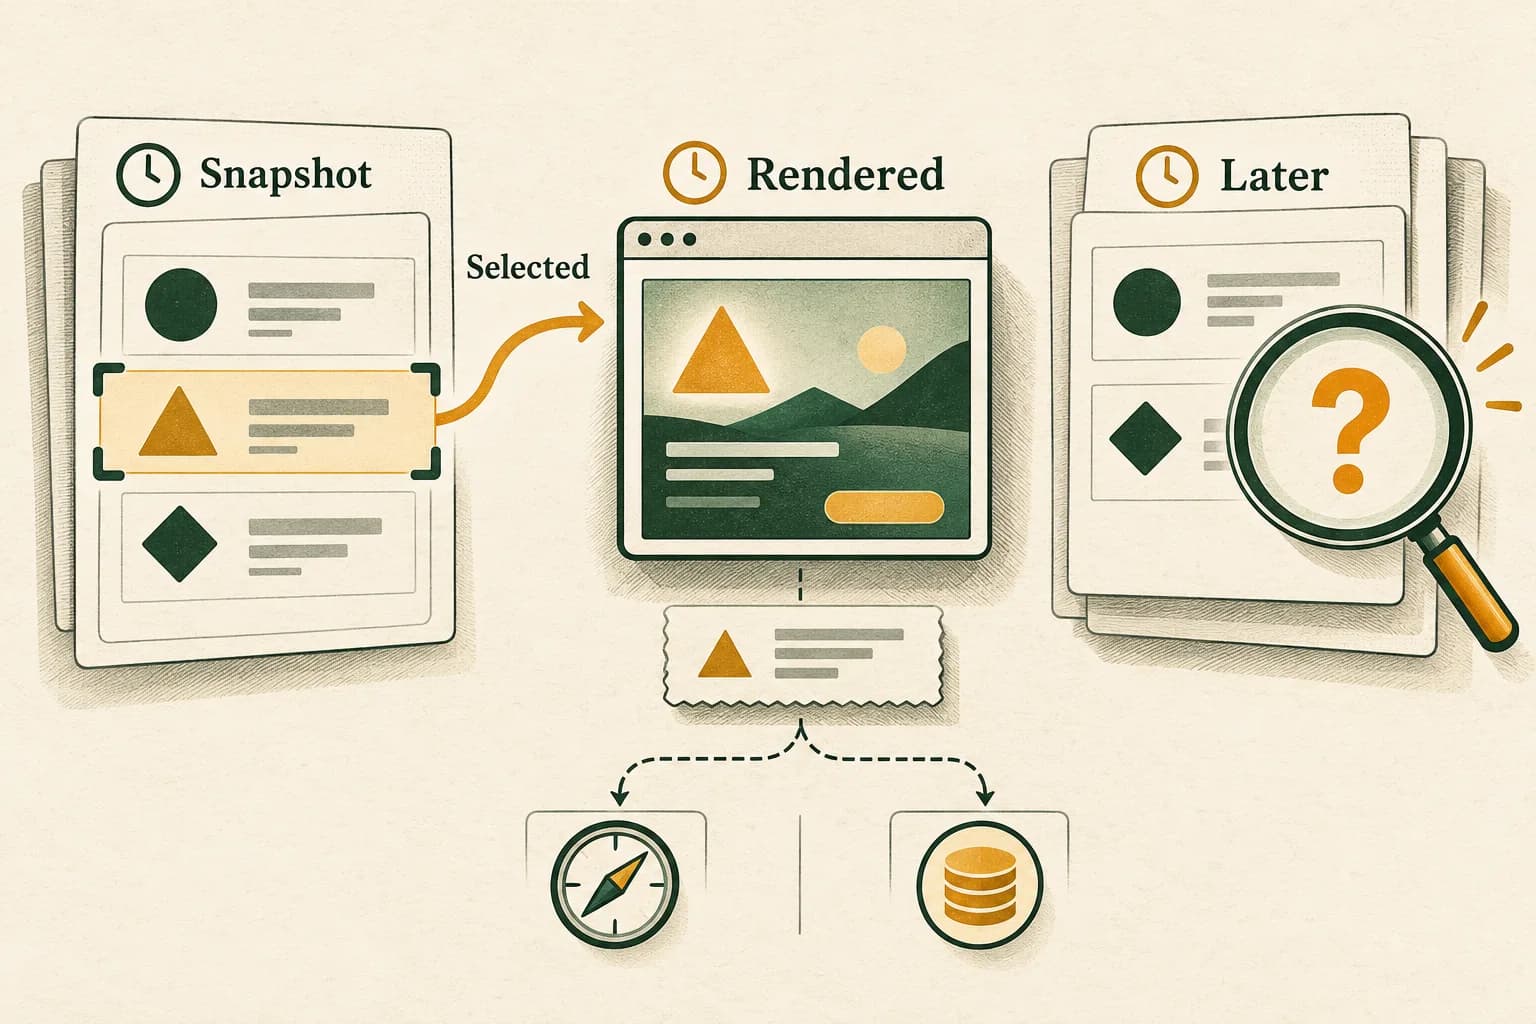
If the ad that rendered does not seem to match the highest Prebid bid, freeze the selection result before rendering and trace its bid identifier into the render call. A later query is a different observation. Also confirm which component chooses the creative: your custom page code, an ad server or another supported integration.
This distinction matters in a real question about Prebid not choosing the highest bid. Replies initially assume an ad server, but the original poster explicitly says there is none and identifies getHighestCpmBids() as the selection method. The archived thread does not prove a resolved cause. Its useful diagnostic task is a custom selection-to-render handoff, not a generic GAM pricing problem.
Do not start by increasing timeouts, overriding a winner or rewriting bid prices. First establish the candidate population, selection policy, chosen identifier and subsequent render evidence for one controlled opportunity.
Identify who actually makes the final decision#
Draw a short path for the running integration:
Auction result -> selection owner -> selected bid reference
               -> render owner -> observed render outcome
               -> separate measurement/reporting outcome
A custom renderer can make the choice directly. A traditional header-bidding integration may instead send targeting to an ad server, which makes another decision. A player or specialized format can introduce another supported handoff. Confirm the actual path rather than inferring it from the presence of Prebid on the page.
| Evidence | Question it answers |
|---|---|
| Running build and wrapper version | Which implementation contract applies? |
| Auction and ad-unit references | Which opportunity is being compared? |
| Snapshot before selection | Which candidate records were visible then? |
| Selection function and policy | What did the page intend to optimize? |
| Selected bid reference | Which record did the implementation choose? |
| Render invocation and outcome | Which record reached the renderer? |
| Measurement receipt | What was subsequently recorded, within coverage? |
For an ad-server report comparison, use the Prebid/GAM reporting guide. A request key or a configured bucket is not a custom-renderer receipt. Keep those separate tasks separate in the incident record.
Trace the selected bid into rendering
Record the auction snapshot, bid identifier and component choosing the creative.
Use the tracking QA checklistOpens a practical guide. No email required.
Understand what the selection APIs return#
Prebid's getHighestCpmBids documentation describes a winning-bid array for each ad unit, or the requested unit when its code is supplied. It also states that, from Prebid 3.0 onward, rendered bids are excluded. Re-running the method after rendering is therefore not a reliable reconstruction of the earlier selection result.
Capture the result at the actual decision boundary. Record the API name, arguments, unit, time and selected identifiers before passing a candidate onward. Keep that snapshot separate from later queries and observations from other units.
A common investigation mistake is to use a page-wide array as though it contained one global winner. Another is to inspect a later console result without knowing which render or subsequent auction happened in between. Neither observation alone demonstrates that Prebid selected a lower bid incorrectly.
Where code uses a custom sort or chooses the first returned record, ask the implementation owner to explain the intended unit and eligibility rules. Do not replace that logic with an unreviewed snippet until the failed boundary is clear.
Compare adjusted CPM and desirability deliberately#
The bid-response reference says its CPM has bid-CPM adjustments applied but is not price-granularity quantized. It exposes the bid's currency, media type, size and identifiers. Preserve those fields together; do not apply an adjustment a second time because a debug screenshot contains another price column.
Current Prebid also documents getBestBids, available from 11.43.0. It selects by desirability rather than necessarily by CPM. Its documentation explains adjusted CPM as the default desirability and the optional configured scoring adjustment. This is a version-specific selection choice, not an instruction to replace every existing call.
Ask which policy the integration actually uses and why. If the business requirement is highest adjusted CPM, test against that defined comparison. If the implementation intentionally ranks desirability, preserve the scoring policy and applicable version. A lower monetary amount under an explicit alternative policy is not automatically a selection defect.
For each candidate, record the available monetary basis, currency, adjustments and applicable eligibility. Do not compare one bidder's raw gross quote against another's normalized adjusted CPM or mix amounts from different units.
Tie the snapshot to the auction that produced it#
Prebid's requestBids reference documents the auction result's bid data, timeout state and auction identifier. The callback boundary matters: a later page-wide query can be affected by other activity. Preserve the selected opportunity's result rather than guessing that all rows in a console view belong to it.
Record all relevant callback paths. Can a timeout path and a later response path both invoke selection? Can a route transition or a second wrapper start another auction for the same placement? These are hypotheses to test, not assertions about the forum question.
Use the auction-to-request timing audit when a handoff occurs too late or targets the wrong slot. Here the narrower question is whether the selected record and rendered record match. “The higher bid arrived first” does not answer that identity question on its own.
Keep version-specific behavior explicit. Do not copy callback assumptions from a different release or treat a callback with missing evidence as a successful completed auction. Ask the integration owner to explain its abort, timeout and error handling.
Inspect a small read-only candidate snapshot#
In an authorized QA session, the following diagnostic reads bid-response metadata for one known ad unit. It does not request bids, choose a winner or render an ad. Replace the placeholder with the test unit and confirm the running API version with its owner.
const unit = "qa-placement";
const entry = pbjs.getBidResponses()[unit];
const bids = Array.isArray(entry) ? entry : (entry?.bids ?? []);
const observedAt = performance.now();
const snapshot = bids.map((bid) => ({
  observedAt,
  adUnitCode: bid.adUnitCode,
  adId: bid.adId,
  bidder: bid.bidder,
  cpm: bid.cpm,
  currency: bid.currency,
  mediaType: bid.mediaType,
  size: bid.size
}));
console.table(snapshot);
The current bid-response documentation describes arrays with a backward-compatible .bids property. The diagnostic handles both shapes, but it is still only an observation at that instant. It does not establish that every displayed candidate was eligible under the actual selector or that it belongs to the intended comparison without the auction context.
Capture the decision function's own result alongside this candidate snapshot. Use a small explicit field projection rather than dumping complete creative markup, URLs or user-related payloads into a shared ticket. Preserve missing fields as missing, and redact the diagnostic export before sending it outside the approved team.
Follow the chosen identifier into the renderer#
Prebid's renderAd reference takes the bid identifier and a rendering document. It warns against using the parent page document for that asynchronous document-write path. The supported rendering context is part of the contract; selection and destination are different checks.
If the correct selected identifier reaches a renderer that fails only in an isolated container, check SafeFrame compatibility separately.
Inspect which selected adId the implementation passes onward, which placement owns the destination and whether another callback can replace it. A matching bidder name is insufficient because one bidder can return several records across units or cycles.
Then inspect the outcome. The Prebid event reference includes auction, bid and render events. It explicitly notes that render-function success does not guarantee tracking has occurred. Keep a successful invocation, rendered creative and accepted measurement receipt distinct.
Do not call renderAd again simply to see whether the top bid appears. Re-rendering or overriding an existing creative changes the situation being investigated and may create unintended delivery. Use the integration's approved test mechanism, preserving the original control.
Two hypothetical explanations to test separately#
Hypothetical snapshot example. Assume one authorized banner opportunity has two comparable, eligible candidates in the same currency and adjusted-CPM policy. These values are invented, not account observations.
| Observation | Candidate A | Candidate B |
|---|---|---|
| Before selection | USD 3.20 CPM | USD 2.80 CPM |
| Chosen identifier | A | Not chosen |
| Renderer receives | A | Not rendered |
| Later selection query | Already rendered, excluded | May remain available |
A later result showing B does not contradict the earlier record showing A was selected and rendered. The comparison fails if it treats the later candidate list as the original one. This is a plausible diagnostic scenario supported by the documented exclusion, not a finding about the forum poster's code.
Now consider a separate hypothetical adjustment example. A raw quote of USD 3.20 CPM is subject to an explicitly configured factor of 0.90, producing USD 2.88 CPM. Another comparable candidate has adjusted CPM of USD 3.00. Under the assumed adjusted-CPM policy, 3.00 exceeds 2.88 by USD 0.12 CPM, despite the first raw quote being numerically higher.
Do not apply that factor again to a response CPM that already reflects it. Nor does the calculation establish a partner's payable rate, net revenue or lost earnings. It only illustrates why the comparison must name its monetary basis.
Choose the next action from the first mismatch#
| Finding | Next investigation |
|---|---|
| Candidates belong to different units or cycles | Correct the comparison scope |
| Later query excludes an already-rendered record | Use the frozen pre-render snapshot |
| Reported price bases differ | Normalize the documented adjustment and currency basis once |
| Policy intentionally ranks desirability | Review the configured scoring requirement and version |
| Selected ID differs from renderer input | Inspect callback state and destination mapping |
| Matching ID reaches renderer but fails | Inspect the supported creative/rendering path |
| Rendering succeeds but measurement is absent | Trace tracking and reporting separately |
Make the correction as narrow as the evidence. A selection-state defect does not require changing every bidder, and a report gap does not justify overriding the rendering path. Retain old and new configuration, expected behavior, approved test scope and rollback owner.
After a fix, compare the same defined boundaries in the control and affected scenarios. A different creative image is not enough: match identifiers and supported outcome records. If some evidence is unavailable, keep the remaining conclusion bounded rather than declaring campaign-wide closure.
Frequently asked questions#
Why does getHighestCpmBids show a different bid after rendering?
Rendered bids are excluded under the documented behavior from Prebid 3.0 onward. Preserve the result before rendering and treat the later query as a separate observation.
Is the highest raw CPM always the intended winner?
Not necessarily. Compare adjusted CPM, currency, eligibility and the actual selection policy. A configured desirability score can express another ordering; verify the deployed version and requirement.
Does using getHighestCpmBids prove an ad server chose the winner?
No. The original question explicitly used custom selection without an ad server. Trace the actual selection and rendering owners instead of assuming the architecture.
Does a successful render event prove a counted impression?
No. Render-function success and tracking/report acceptance are separate boundaries. Inspect the measurement receipt within its actual coverage.
Compare the delivery evidence within its scope#
The anonymized fashion retail display case illustrates the value of a documented delivery baseline. It does not validate a custom Prebid selector or establish that another candidate would have earned more.
Where the campaign is measured by AdProof, compare available event or aggregate exports with the publisher's same-scope delivery records, dates and timezone. Keep the auction snapshot and renderer evidence with the implementation owner. Discuss the campaign-delivery comparison without assuming an independent export can reconstruct an unrecorded selection decision or configure the page's renderer.
Trace the selected bid into rendering
Record the auction snapshot, bid identifier and component choosing the creative.
Use the tracking QA checklistOpens a practical guide. No email required.