
- Published
- Oct 30, 2026
- Updated
- Oct 31, 2026
- Reading time
- 12 min read
Prebid + GPT Lazy Loading: Audit SRA and Ad Timing
Diagnose slow lazy-loaded ads by tracing Prebid auctions, GPT targeting, SRA requests and rendering. Separate HTTP counts, slot events and measured impressions.
In this guide (12 sections)
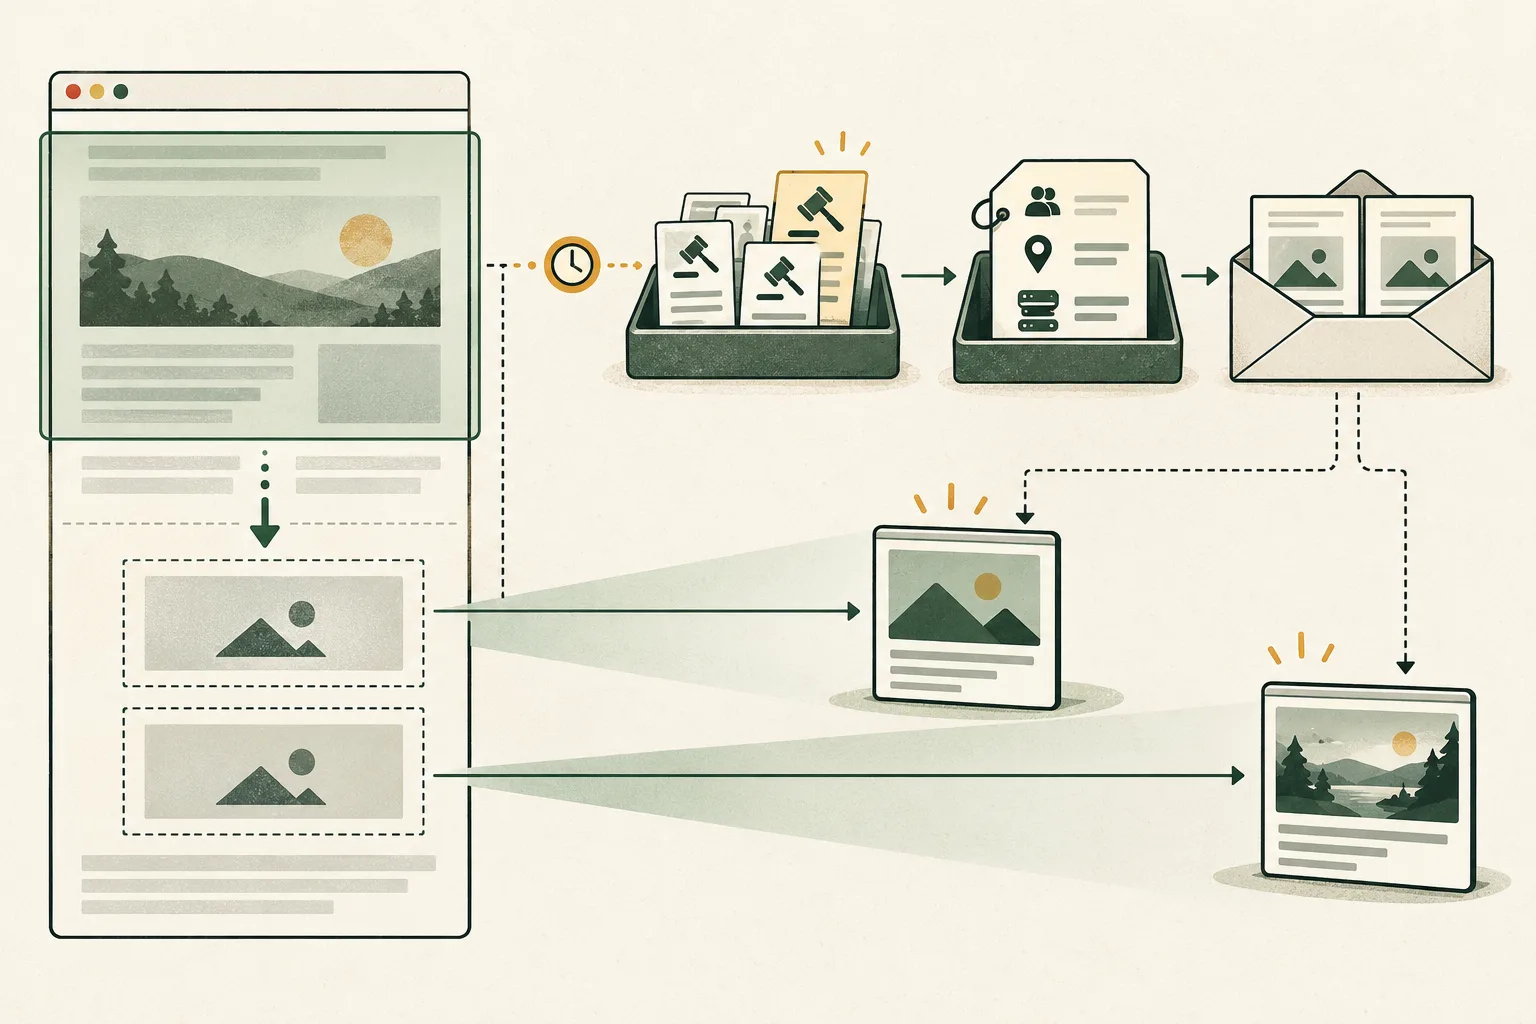
When lazy-loaded ads appear late, separate when the auction starts, when its targeting reaches GPT, when GPT requests the ad, and when the creative renders. Single Request Architecture, or SRA, groups requests for slots; it does not make those stages interchangeable or guarantee that every grouped slot is immediately visible.
A real publisher question about slow Prebid and GAM requests grouped in pairs asks how lazy bidding and lazy loading should work together. An earlier question from the same author asks whether grouping slots eliminates native GPT lazy loading. These are older evergreen implementation questions, counted as one author's repeated problem rather than independent demand.
The useful answer is an event trace and an ownership decision, not a universal pixel offset or a rule to remove SRA. Keep the approved consent behavior and the actual ad-serving arrangement intact while finding the first late or missing handoff.
Start with four different clocks#
For one slot and one request cycle, capture these observations:
| Boundary | Evidence to retain | What remains separate |
|---|---|---|
| Auction trigger | Scroll or application condition, time and included ad-unit codes | An actual bidder request or response |
| Auction outcome and targeting | Auction ID, callback outcome and keys applied to the intended GPT slot | Final ad-server selection |
| GPT request and response | Slot identity, request cycle and response observations | A completed creative load |
| Render and measurement | Creative injection, load and supported measurement events | A guarantee of viewer attention or revenue |
Give each cycle its own identifier in the diagnostic record. An infinite-scroll page can reuse a placement name across several logical opportunities. A screenshot of the current targeting may describe a later cycle than the request you are investigating.
Preserve the page release, Prebid build and modules, GPT setup, wrapper version, viewport size, test device and relevant loading rules. Determine whether the inspected page is actually running the configuration the team thinks it deployed.
Trace the auction and request clocks
Record when bidding starts, targeting reaches GPT and the creative renders.
Use the tracking QA checklistOpens a practical guide. No email required.
Understand what GPT lazy loading and SRA actually combine#
Google's lazy-loading sample explicitly supports lazy loading with SRA. In that sample's arrangement, the first slot reaching the fetch margin triggers the request for that slot and the other slots. A later slot can therefore be requested before it reaches its own visible position.
That is different from saying that all creative resources must immediately render, or that every slot has already qualified as a viewable impression. Inspect the actual request group and rendering behavior rather than diagnosing premature loading from one network entry.
Google's ad-slot best practices describes SRA as bundling multiple slot requests into one request and recommends configuring slots before the initial request. It also explains SRA's role in page-level competitive exclusions and roadblocks. Removing it merely to reduce confusion can change the delivery contract you intended to preserve.
Write down which behavior your page needs: early above-the-fold delivery, deferred below-the-fold rendering, coordinated ad selection, or a new group introduced by infinite scroll. Those requirements may need different request groups. They do not establish that every page should use one identical wrapper design.
Do not compare HTTP calls with slot events as equal units#
The GPT SlotRequested reference states that each slot fires the event even when slots are batched in a single SRA request. That gives you a direct reason why a browser's HTTP-request count and a slot-level request count can differ without a defect.
Name the unit in every worksheet:
- HTTP requests sent to the ad server.
- Slot request cycles represented by those requests.
- Slots receiving responses, including empty outcomes where exposed.
- Non-empty creative outcomes and subsequent loading observations.
- The named impression or viewability metric in a particular report.
Do not call all five “requests” or “impressions.” A reduction in HTTP calls can leave the same slot population intact. Likewise, a received response is not proof that a creative became visible on the user's screen.
For the same reason, neither a page-view total nor a Prebid auction count is automatically the denominator of a GAM fill or viewability metric. Keep metric names and population definitions copied from the owning report.
Audit registration and the first request#
Google's control-ad-loading guide separates registration from loading. With googletag.setConfig({ disableInitialLoad: true }) configured before services are enabled and before display(), the display call registers the slot without automatically requesting content. A later refresh() can perform its first load; that method is not limited to replacing an existing ad. For later creative replacement, compare the deployed refresh trigger and minimum interval with the GAM declaration. A refresh API call and an inventory declaration are separate controls.
Use that reference to inspect your existing arrangement, not as an instruction to paste a second configuration onto a live page. Establish which component owns the first request. Look for both a default load and a wrapper-triggered load reaching the same intended opportunity.
The same guide distinguishes refreshing an explicit slot array from calling refresh() without parameters, which affects all registered slots. If the wrapper intended to load one new pair, preserve the actual slot array passed by that cycle. A later unrelated slot event does not prove that the pair triggered correctly. For a grouped roadblock, verify the intended creative set and its impression-counting basis as well as the slot request. Request grouping does not by itself promise equal counts for every creative.
Keep the timing of slot configuration visible. Targeting that arrives after the request has already left cannot retroactively alter that request. Inspect the actual outgoing evidence before calling an apparently correct later console state a passed test.
Match the Prebid auction to the GPT slots it should serve#
Prebid's requestBids reference allows selecting specific ad units or codes; omitting those selections requests bids for the added units. Its callback describes responses returning or the auction timeout being reached. That callback is an auction checkpoint, not proof that GPT requested or rendered an ad.
Record the actual included codes, auction ID, timeout outcome and relevant response times. If the page intends to lazy-auction one group, confirm that the request was scoped to that group instead of inferring scope from the function's location in the source.
Prebid's GPT targeting reference describes matching auction ad units to GPT slots and applying the hb_ targeting. Verify the mapping among the ad-unit code, GPT slot and HTML container for the tested cycle. Keep this distinct from a bidder winning the eventual ad-server decision. If a custom renderer appears to show a different bid, audit the actual selection-to-render handoff. Preserve the unit, auction context, adjusted monetary basis and chosen bid reference before rendering changes the available candidate set.
Then compare the time targeting was applied with the time GPT requested the same slot. If the order is wrong, preserve the sequence and ask the wrapper owner to review the supported orchestration. Do not hide the symptom by adding arbitrary sleeps or triggering every bidder again.
The Prebid versus GAM reporting guide owns the separate question of how targeting keys appear in bidder and revenue reports. A valid key or price bucket is not an end-to-end rendering trace.
Capture the first slow stage, not just the final blank slot#
Use the supported Prebid getEvents interface to inspect emitted auction events and elapsed timing. Match auction and ad-unit identifiers where available. Do not assume that the most recent auction on the page belongs to the slot that appeared late.
Pair that evidence with GPT's ad-event listeners: slot request, response, creative injection, creative load and viewability are separate event boundaries. Attach each observation to event.slot, rather than letting an event from one slot stand in for every slot on the page.
Google's SlotRenderEnded definition says creative code has been injected before its resources are necessarily fetched. It is therefore not a complete “the visitor saw the ad” event. Preserve the later supported load and measurement findings without converting an absent signal into a fabricated zero.
A practical trace answers four questions:
- Did the relevant auction start early enough for this actual journey?
- Were its intended keys on the slot before the corresponding request?
- Did the ad-server response arrive, and was its outcome empty or non-empty?
- Did the selected creative's resources and measurement path then complete?
A slow response or resource load needs a different owner from a trigger that never ran. A supported no-ad response needs a different investigation from both.
Choose margins from evidence, not a forum constant#
The GPT lazy-load configuration reference distinguishes fetch and render margins, expressed as percentages of viewport size, and a mobile scaling multiplier. Those values are not interchangeable with a wrapper's pixel-based scroll threshold.
Record the units before comparing configurations. Also capture the observed viewport, scroll behavior and latency distribution on representative devices. The same numeric value can describe very different physical lead distances or runtime budgets.
Start by reproducing one late path and a comparable working path. Check whether the delay is dominated by triggering, auction completion, the ad-server response or creative loading. Test an authorized, scoped change against that finding, retaining the same consent branch and request population.
Earlier triggering can create more time before a slot enters view, but may also fetch for visitors who never reach it. Later triggering can conserve work while leaving less time to complete the path. Evaluate both delivery timing and the defined opportunity population; neither strategy promises revenue growth or universally better viewability.
A worked timing and counting example#
Hypothetical teaching example. These invented timings represent one authorized test journey, not a recommended production timeout or customer result.
| Observation for slot A | Time after its trigger |
|---|---|
| Prebid auction begins | 0 ms |
| Auction callback completes | 650 ms |
| Relevant targeting applied | 700 ms |
| GPT request observed | 720 ms |
| Slot reaches the viewport | 750 ms |
| Ad-server response received | 900 ms |
| Creative injection observed | 1,050 ms |
The request began 30 milliseconds before viewport entry, and injection occurred 300 milliseconds after entry. The 70 milliseconds from auction callback to request and the later 330 milliseconds from request to injection belong to different parts of the trace. Injection still does not prove that all creative resources have finished.
Suppose the page records two SRA HTTP requests covering four slot request cycles. Three responses are non-empty and one is empty. Comparing two HTTP calls with four slot events would manufacture a discrepancy. Separately, three non-empty responses do not establish three viewable impressions or a final payable amount.
If a controlled test moves the trigger earlier, compare the new sequence and the opportunities fetched but never reached. Do not attach the entire change in an account's revenue to that one timing adjustment.
Keep subsequent refreshes from reusing the wrong evidence#
Prebid's individual-unit refresh example warns that directly refreshing GPT without updated Prebid targeting can repeatedly reuse the same bids. Its example also notes that its demonstration build is not recommended for production.
For a repeated load, identify the intended cycle, auction or supported reuse policy, targeting applied and precise GPT slot set. Do not assume every refresh needs the same auction settings, or that a copied demonstration page is a production wrapper. When fallback replaces an already-filled placement, trace the callback’s slot and active lifecycle. An empty response elsewhere or a stale delayed action is not permission to overwrite the current creative.
This is an audit of what the implementation does, not an instruction to increase refresh frequency. Leave policy declarations and commercial requirements with their owners. If consent discovery is the first missing boundary, use the existing Prebid CMP timing guide rather than changing the request loop to bypass it.
Close the test with a bounded finding#
| Finding | Useful next action |
|---|---|
| SRA fetches a lower slot earlier than expected | Confirm actual batch membership and separate rendering behavior |
| The intended auction does not run for the slot | Review trigger and ad-unit selection |
| GPT requests before the relevant targeting is applied | Review first-load ownership and orchestration |
| Targeting exists but maps to another slot | Correct and retest the identified mapping |
| Response is non-empty but resources load late | Inspect the selected creative's resource path |
| Counts differ only because HTTP and slot units differ | Correct the worksheet's units before investigating loss |
Retain the released versions, slot/cycle identifiers, ordered events, tested correction and remaining unknowns. Use the publisher revenue diagnostic for a broader account earnings change after the request and rendering boundaries are understood.
For campaigns already measured through AdProof, keep a supported campaign-event or aggregate export with matching dates, timezone and filters alongside the independently obtained page and wrapper evidence. The anonymized fashion-retail delivery case concerns measured campaign quality, not a native Prebid debugger or a lazy-loading revenue uplift. Discuss the available delivery evidence before assuming the wrapper or page lifecycle is independently covered.
Frequently asked questions#
Does SRA prevent GPT lazy loading?
No. Google's sample explicitly combines them. Inspect when the group is fetched and when individual creatives render instead of treating a grouped request as immediate visibility for every slot.
Should one SRA HTTP request equal one slotRequested event?
No. GPT documents slot-level events even when several slots are batched in one request. Compare the same unit and request population.
Does a Prebid auction completing prove the ad appeared?
No. Targeting, the ad-server request and response, creative loading and measurement still need their own evidence. A timeout callback also requires its actual outcome to be read.
What is the best lazy-load distance or timeout?
No universal value is established here. Record the configuration units, device conditions and first slow stage, then test a scoped change without claiming a margin guarantees viewability or revenue.
Research and scope#
Reviewed 30 October 2026. The two original questions are older reports from the same author. Historical snippets, suggested offsets and claimed performance are not current implementation instructions or benchmarks. Official GPT and Prebid references were opened during research. The workflow and example are diagnostic recommendations, not an executed publisher audit or a guaranteed optimization.
Trace the auction and request clocks
Record when bidding starts, targeting reaches GPT and the creative renders.
Use the tracking QA checklistOpens a practical guide. No email required.